
Assure your AI deployment - across enterprise and real world
We assure that your AI works as intended. Safely and securely.


Pairwise Testing: How It Works, PICT Example and Tools
Pairwise testing covers every pair of input values in a fraction of the tests. Learn it with real PICT output, constraints, a coverage check and a grid run.
Last Updated on:
Say a checkout page has to work on four browsers, two browser versions, three operating systems and three screen resolutions. That is 72 configurations before a single test input changes, and some of them, such as Safari on Windows, cannot run at all.
Pairwise testing cuts a matrix like that down to the few rows that still pair every value with every other value at least once. For this exact matrix, Microsoft's PICT generator produced 12 rows, and all 12 ran as parallel Selenium sessions in about 30 seconds.
The case for covering pairs comes from NIST's combinatorial testing research, which found that between 70 and 95 percent of software failures are triggered by only two variables interacting.
Overview
Pairwise testing, also called all-pairs testing, is a test design technique that picks a small set of test cases in which every pair of input values appears at least once. Because NIST found most software failures are triggered by two interacting variables, covering every pair reaches most interaction bugs with far fewer tests than exhaustive testing.
What Does Pairwise Testing Save?
- Fewer test cases: In PICT 3.7.4 runs, 10 parameters with three values each (59,049 combinations) needed 18 pairwise tests, and 20 such parameters needed only 24.
- Provable pair coverage: Every value pair appears in at least one test, which a short script can check; a 12-test suite for 4 browsers, 2 versions, 3 operating systems and 3 resolutions covers all 50 valid pairs.
- No impossible rows: Constraints such as "Safari runs only on macOS" keep invalid combinations out, cutting the browser matrix from 72 raw combinations to 57 valid ones before reduction.
Which Tools Generate Pairwise Tests?
- PICT: Microsoft's MIT-licensed command-line generator (cost: free, interface: CLI) that reads a plain-text model, supports IF/THEN constraints and raises the order with its /o switch.
- ACTS: NIST's Java tool (cost: free, interface: GUI and command line) that generates t-way test sets from 2-way upward and supports constraints between parameters.
- allpairspy: An MIT-licensed Python library (cost: free, interface: Python code) that yields pairwise rows inside test code and rejects invalid rows through a filter function.
- Hexawise: A commercial test design tool from Idera (cost: paid licenses, interface: web) that builds combinations of test conditions, with pricing through sales and a trial on request.
- TestMu AI: A cloud grid of 3,000+ browser/OS combinations that runs each generated row as its own parallel Selenium session; a 12-row pairwise browser suite took about 30 seconds per run.
What Is Pairwise Testing?
Pairwise testing, also known as all-pairs testing, is a software testing technique that selects test cases so every possible pair of values from any two input parameters appears together in at least one test. It is a black-box testing method: it works from the inputs and their allowed values, not from the code, and sits alongside the other test case design techniques.
Take a login page checked on two browsers, two operating systems and two languages. Every combination takes eight runs, yet these four rows cover every browser-OS, browser-language and OS-language pair:
| Test | Browser | OS | Language |
|---|---|---|---|
| 1 | Chrome | Windows | English |
| 2 | Chrome | macOS | French |
| 3 | Firefox | Windows | French |
| 4 | Firefox | macOS | English |
Each row tests three pairs at once, which is where the savings come from. The floor for any pairwise suite is the product of the two largest value counts, because each of those value pairs needs its own row; adding more parameters raises the count only slowly, as the next section measures.
Pairwise vs Exhaustive Test Counts
I generated suites with PICT 3.7.4 for models of 3 to 20 parameters, each with three values, and counted the rows. The exhaustive column is every combination; the 3-way column covers every triple of values instead of every pair.
| Parameters (3 values each) | Exhaustive combinations | Pairwise tests (PICT) | 3-way tests (PICT /o:3) |
|---|---|---|---|
| 3 | 27 | 10 | 27 |
| 4 | 81 | 13 | 34 |
| 5 | 243 | 12 | 43 |
| 6 | 729 | 14 | 48 |
| 8 | 6,561 | 16 | 59 |
| 10 | 59,049 | 18 | 65 |
| 13 | 1,594,323 | 20 | 77 |
| 15 | 14,348,907 | 21 | 83 |
| 20 | 3,486,784,401 | 24 | 94 |
The pairwise count is not strictly increasing: four parameters produced 13 rows and five produced 12, because PICT builds suites with a greedy search rather than an exact construction. What matters in practice is the gap: each added parameter triples the exhaustive count, while the pairwise count never grew by more than three rows from one table row to the next.
- Shorter runs - a 20-parameter model needs 24 sessions or manual passes instead of a number no team could execute.
- Coverage by construction - every pair is covered because the generator guarantees it, not because someone picked "representative" configurations by hand.
- Cheap to extend - going from 8 to 10 parameters in the table added two rows, so a new browser version or locale rarely forces a rethink of the suite.
When Should You Use Pairwise Testing?
Pairwise testing pays off when several independent parameters each take a few values and a bug needs two specific values together to appear. Typical fits:
- Configuration matrices - browser, version, OS and resolution in cross-browser testing. The pairwise test technique for cross-browser testing covers that case in more depth.
- Form and API inputs - fields such as payment method, country and shipping option, or the request parameters in web services testing.
- Feature flags - each flag is a two-value parameter, and PICT covered every pair of 10 on/off flags (1,024 combinations) in 9 rows.
- Locale settings - language, region, currency and date format in localization testing, where each setting has a short list of supported values.
How to Perform Pairwise Testing
The walkthrough uses the browser matrix from the introduction. Every model, output and result below came from runs on October 23, 2026, with PICT 3.7.4, Node.js 24 and selenium-webdriver 4.46.0.
Step 1: Model the Parameters and Values
List each input that can change independently, then cut each one down to a few representative values. Equivalence partitioning picks one value per class and boundary value analysis adds the edges; pairwise testing then decides which combinations of those values to run.
Browser:    Chrome, Firefox, MicrosoftEdge, Safari
Version:    latest, latest-1
Platform:   Windows 11, Windows 10, macOS Sequoia
Resolution: 1280x1024, 1920x1080, 2560x1440
The values are written exactly as the TestMu AI grid expects them in the browserName, browserVersion, platformName and resolution Selenium automation capabilities, so each generated row can go straight into a session request.
Step 2: Add Constraints for Invalid Combinations
Safari runs only on macOS, and the grid rejected a request for Safari latest-1 on macOS Sequoia with "Could not find a valid browserVersionData". Constraints at the end of the model encode both limits:
IF [Browser] = "Safari" THEN [Platform] = "macOS Sequoia";
IF [Browser] = "Safari" THEN [Version] = "latest";
Without them, 15 of the 72 raw combinations would schedule a Safari session that cannot start. With them, pict grid-model.txt /o:max lists the 57 valid combinations in full, which step 4 uses as the reference.
Step 3: Generate the Suite With PICT
PICT is Microsoft's command-line test case generator: on Windows you download pict.exe from the releases page, and on Linux and other Unix-like systems you build it from source with CMake.
Running it on the model printed this suite:
> pict grid-model.txt > suite.tsv
Browser	Version	Platform	Resolution
MicrosoftEdge	latest	Windows 11	1280x1024
Chrome	latest-1	Windows 10	1280x1024
Safari	latest	macOS Sequoia	1920x1080
Chrome	latest-1	Windows 11	1920x1080
Firefox	latest	Windows 10	1920x1080
Safari	latest	macOS Sequoia	1280x1024
Chrome	latest	macOS Sequoia	2560x1440
Firefox	latest-1	Windows 11	2560x1440
MicrosoftEdge	latest-1	macOS Sequoia	1920x1080
MicrosoftEdge	latest	Windows 10	2560x1440
Firefox	latest-1	macOS Sequoia	1280x1024
Safari	latest	macOS Sequoia	2560x1440
That is 12 tests in place of 57. The /s switch reports "Combinations: 50", which is the number of value pairs to cover, not the number of full combinations. PICT's default output is deterministic, so regenerating an unchanged model gives the same rows; add /r to randomize, which on a three-parameter model gave 9 or 10 rows depending on the seed.
Step 4: Check Pair Coverage
A hand-edited row or a deleted test silently breaks coverage, so verify it. Save this as check-pairs.js; it collects every pair that appears in at least one valid combination and reports any the suite misses:
const fs = require("fs");
const read = (file) => fs.readFileSync(file, "utf8").trim()
  .split(/\r?\n/).slice(1).map((line) => line.split("\t"));
const pairsIn = (rows) => {
  const pairs = new Set();
  for (const row of rows)
    for (let i = 0; i < row.length; i++)
      for (let j = i + 1; j < row.length; j++)
        pairs.add(i + "=" + row[i] + " & " + j + "=" + row[j]);
  return pairs;
};
const [allFile, suiteFile] = process.argv.slice(2);
const needed = pairsIn(read(allFile));
const covered = pairsIn(read(suiteFile));
const missing = [...needed].filter((pair) => !covered.has(pair));
console.log(read(suiteFile).length + " tests cover " +
  (needed.size - missing.length) + " of " + needed.size + " valid pairs");
if (missing.length) { console.log("Missing:", missing); process.exit(1); }
> pict grid-model.txt /o:max > all.tsv
> node check-pairs.js all.tsv suite.tsv
12 tests cover 50 of 50 valid pairsDeleting the last row shows the failure mode. The script then prints "11 tests cover 49 of 50 valid pairs", names the lost pair (Safari with 2560x1440) and exits with code 1, which is enough to fail a CI job.
Step 5: Run the Rows on a Cloud Grid
Each row is one configuration, so the whole suite can run at once. TestMu AI's Automation Cloud runs existing Selenium scripts across 3,000+ browser and OS combinations in parallel, with no local grid to maintain. The script below opens one session per row on the Simple Form Demo, types a message and waits for the page to echo it.
// run-suite.js, part 1 of 3: one TestMu AI session per PICT row
const fs = require("fs");
const { Builder, By, until } = require("selenium-webdriver");
const HUB = "https://hub.lambdatest.com/wd/hub";
const PAGE = "https://www.testmuai.com/selenium-playground/" +
  "simple-form-demo/";

const session = ([browser, version, platform, resolution], n) =>
  new Builder().usingServer(HUB).withCapabilities({
    browserName: browser,
    browserVersion: version,
    "LT:Options": {
      platformName: platform, resolution,
      username: process.env.LT_USERNAME,
      accessKey: process.env.LT_ACCESS_KEY,
      build: "Pairwise Testing Demo", name: "Row " + n,
    },
  }).build();
// run-suite.js, part 2 of 3: the check every row runs
const js = (driver, expr) => driver.executeScript("return " + expr);
// Safari sessions can lose window focus, and a click sent then is dropped
const focused = (driver) =>
driver.wait(() => js(driver, "document.hasFocus()"), 20000);
async function check(driver) {
await driver.get(PAGE);
await driver.wait(() => js(driver, "document.readyState == 'complete'"));
await focused(driver);
const input = await driver.findElement(By.css("input#user-message"));
await input.sendKeys("pairwise");
await focused(driver);
await driver.findElement(By.id("showInput")).click();
const message = await driver.findElement(By.id("message"));
await driver.wait(until.elementTextIs(message, "pairwise"), 10000);
return js(driver, "window.innerWidth");
}// run-suite.js, part 3 of 3: run every PICT row in parallel
async function runRow(row, n) {
const driver = await session(row, n);
let result = "failed";
try {
result = "passed (" + (await check(driver)) + "px)";
} catch (err) {
result += " (" + err.name + ")";
} finally {
await driver.executeScript("lambda-status=" +
(result.startsWith("passed") ? "passed" : "failed"));
await driver.quit();
console.log("Row " + n + " " + row.join("/") + ": " + result);
}
}
const rows = fs.readFileSync("suite.tsv", "utf8").trim()
.split(/\r?\n/).slice(1).map((line) => line.split("\t"));
Promise.all(rows.map((row, i) => runRow(row, i + 1)));With LT_USERNAME and LT_ACCESS_KEY exported, node run-suite.js printed the rows in the order they finished. This run took 28 seconds:
Row 9 MicrosoftEdge/latest-1/macOS Sequoia/1920x1080: passed (1912px)
Row 12 Safari/latest/macOS Sequoia/2560x1440: passed (2560px)
Row 6 Safari/latest/macOS Sequoia/1280x1024: passed (1280px)
Row 3 Safari/latest/macOS Sequoia/1920x1080: passed (1920px)
Row 1 MicrosoftEdge/latest/Windows 11/1280x1024: passed (1256px)
Row 4 Chrome/latest-1/Windows 11/1920x1080: passed (1904px)
Row 5 Firefox/latest/Windows 10/1920x1080: passed (1920px)
Row 8 Firefox/latest-1/Windows 11/2560x1440: passed (2560px)
Row 11 Firefox/latest-1/macOS Sequoia/1280x1024: passed (1280px)
Row 2 Chrome/latest-1/Windows 10/1280x1024: passed (1264px)
Row 7 Chrome/latest/macOS Sequoia/2560x1440: passed (2560px)
Row 10 MicrosoftEdge/latest/Windows 10/2560x1440: passed (2536px)
The pixel figure is window.innerWidth, a quick proof that the resolution capability took effect. Firefox everywhere and Chrome and Safari on macOS report the requested width exactly, while Edge, and Chrome on Windows, come in 8 to 24 pixels narrower, so check for a near match rather than an exact one. Don't use screen.width for this check: on the macOS hosts it reported 3840 whatever resolution was requested.
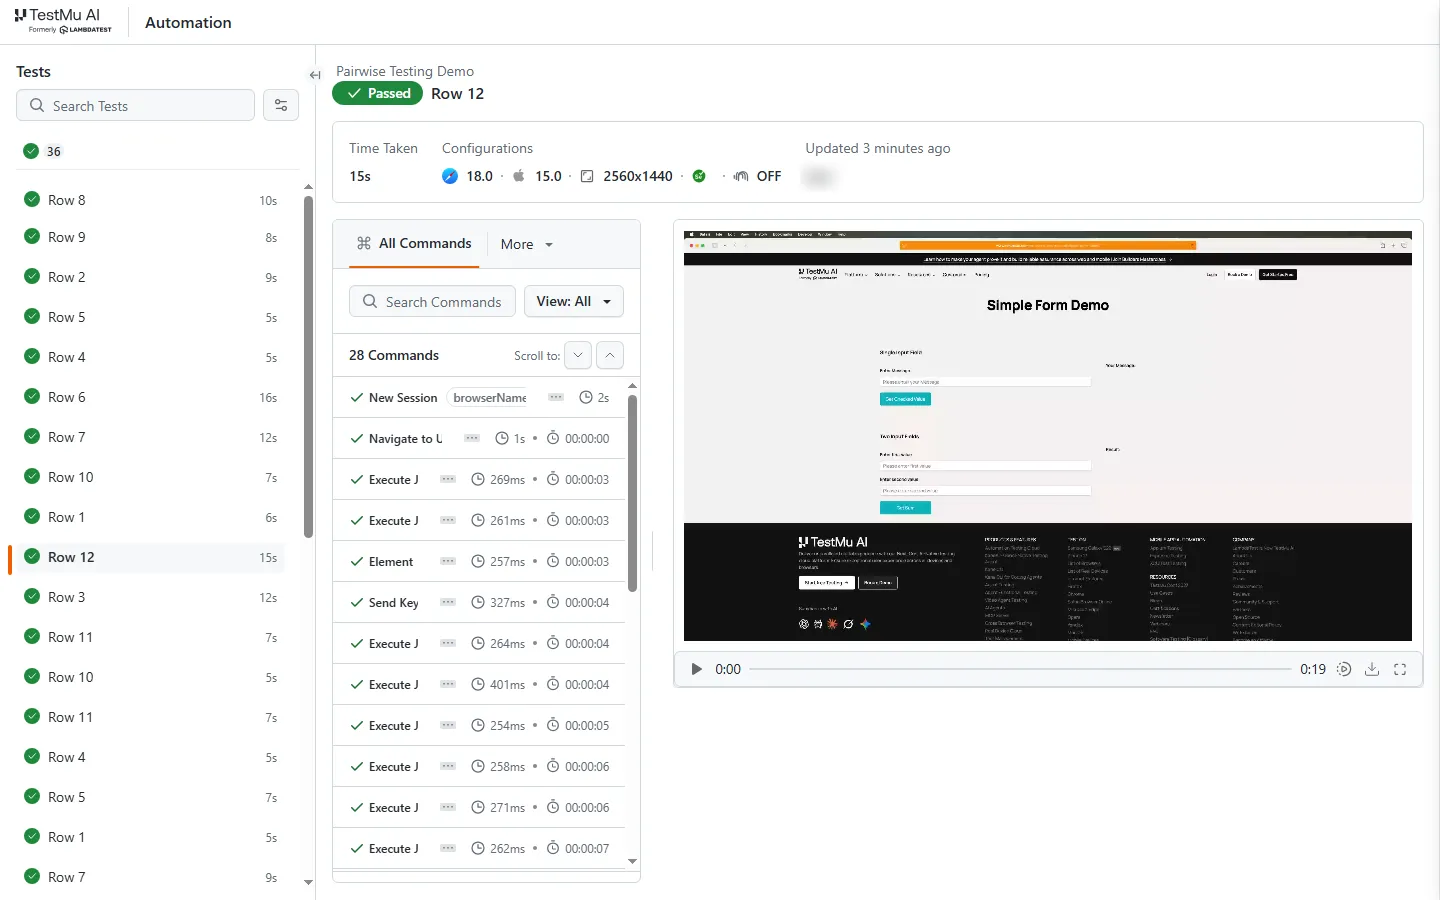
The first runs did not pass cleanly, and the failure pattern is a pairwise lesson in itself. Every failing row was a Safari row, at more than one resolution: the text was typed, but the click that should echo it did nothing. When failures share one parameter value while the other values vary, suspect that value first.
Step-level diagnostics on 12 Safari sessions confirmed it: every failing session had lost window focus between typing and clicking (document.hasFocus() returned false), and every passing one had kept it. Waiting for focus before each interaction, the focused() helper in part 2, fixed it. Three full runs then passed 36 of 36 sessions in build 109517445 on Chrome 154 and 155, Edge 154 and 155, Firefox 156 and 157, and Safari 18.0, at 28 to 30 seconds per run.

Austin Siewert
Co-Founder, Steadfast Systems
Discovered @TestMu AI yesterday. Best browser testing tool I've found for my use case. Great pricing model for the limited testing I do 👏
3M+ Devs and QAs rely on TestMu AI
Deliver immersive digital experiences with Next-Generation Mobile Apps and Cross Browser Testing Cloud

Orthogonal Arrays and Pairwise Generators
An orthogonal array is a table in which every pair of values appears the same number of times for any two columns. The L9 array covers four parameters with three values each in nine rows, every pair exactly once, which is the smallest suite possible for that model:
| Row | P1 | P2 | P3 | P4 |
|---|---|---|---|---|
| 1 | A | A | A | A |
| 2 | A | B | B | B |
| 3 | A | C | C | C |
| 4 | B | A | B | C |
| 5 | B | B | C | A |
| 6 | B | C | A | B |
| 7 | C | A | C | B |
| 8 | C | B | A | C |
| 9 | C | C | B | A |
The coverage script from step 4 prints "9 tests cover 54 of 54 valid pairs" for this array. For the same four-parameter model, PICT's default output had 13 rows and ten seeded runs gave 11 to 13. On the three-parameter model, PICT returned 10 rows where a nine-row Latin square also covers all 27 pairs.
Generators win on flexibility. Standard orthogonal arrays come in fixed sizes such as L4, L8, L9 and L16, so a model with mixed value counts has to be padded to fit one, and the balanced layout leaves no room for constraints like the Safari rule above. PICT accepts both and pays for it with a few extra rows.
N-Wise Testing Beyond Pairs
Pairwise testing is 2-way combinatorial testing. N-wise, or t-way, testing covers every combination of N values: 3-way covers every triple, 4-way every quadruple. The same NIST research found that virtually all failures in the systems it studied were triggered by no more than six interacting variables, and NIST's ACTS tool generates test plans for two to six.
The cost rises fast. For the browser model, /o:3 produced 30 rows against 12 for pairwise and 57 for every valid combination; for 20 three-value parameters it produced 94 rows against 24. Run the full suite pairwise and raise the order only for the features where a three-value interaction has caused a defect before.
At the far end, running every combination is still reasonable when the matrix is small. TestMu AI's HyperExecute does that through its matrix multiplexing strategy, which expands every combination of the values listed in its YAML file and drops invalid ones through an exclusionMatrix block.
Tools for Pairwise Testing
The Pairwise Testing site at pairwise.org keeps a list of available tools with dozens of combinatorial test generators, from command-line programs to web-based tools.
The table covers a mix of free and commercial options, with each fact checked against the project's own page:
| Tool | From | Interface and cost | Worth knowing |
|---|---|---|---|
| PICT | Microsoft | Command line; free, MIT license | IF/THEN constraints, /o for higher orders, /e for seed rows that must appear |
| ACTS | NIST | Java GUI and command line; free | t-way test sets with constraint support; an advanced version is sent on email request |
| Jenny | Bob Jenkins | Command line (C); free | -n sets the tuple size; -w adds "withouts" that exclude combinations |
| AllPairs | James Bach (Satisfice) | Command line, built on a Perl script; free download | Pairwise coverage only; source included |
| allpairspy | Open source | Python library; free, MIT license | Iterator API inside test code; filter function for invalid rows; n-wise on request |
| Hexawise | Idera | Web; commercial licenses, trial on request | Builds combinations of test conditions for test design teams |
ACTS and NIST's other combinatorial tools, including a Combinatorial Sequence Test Generator for event-driven systems, are free on the NIST downloadable tools page.
For Python suites, allpairspy generates the rows inside the test code and filters out invalid combinations during the search for the next one.
Limitations of Pairwise Testing
- Three-value interactions slip through - a bug that needs three specific values together is caught only if one row happens to hold all three. NIST's figure for two-variable failures tops out at 95 percent, so the rest needs 3-way or higher.
- The model is the coverage - pairs are guaranteed only among the values you listed. An older browser version or an empty input that never made it into the model is never tested.
- Constraints cut both ways - a missing constraint wastes rows on impossible combinations, while an over-broad one removes valid pairs from the suite and from the reference file alike, so the coverage check cannot see it. Review constraints by hand.
- No expected results - the generator picks inputs, not outcomes. Each row still needs an assertion, such as the echoed message in step 5.
- Order and rules are out of scope - pairwise treats parameters as unordered values, so sequence-dependent flows need sequence covering arrays, and rule-heavy logic is better modeled with a decision table.
Pairwise Testing Best Practices
| Practice | Why it matters | How to do it |
|---|---|---|
| Keep value lists short | The suite can never be smaller than the two largest value counts multiplied together | Group a long list into equivalence classes and test one value per class |
| Write constraints first | Impossible rows fail for reasons unrelated to the product | Encode platform limits in the model, as in step 2 |
| Commit the model, not just the output | The model is the reviewable source of the suite | Keep model.txt next to the tests and regenerate when values change |
| Check coverage in CI | Edits to the generated suite can drop pairs silently | Run check-pairs.js after generation and fail the job on exit code 1 |
| Seed must-run rows | Your highest-traffic configuration may not appear in the generated rows | Pass PICT a seeding file with /e so those rows are always included |
| Track results per row | A failure that repeats on one value, like Safari in step 5, is only visible row by row | For manual passes, TestMu AI's test management platform can hold one test cycle per environment, each with its own pass, fail and blocked status |

Note: Run the 12-row suite from this guide on your own account: sign up, export LT_USERNAME and LT_ACCESS_KEY, and start run-suite.js unchanged. Sign up for TestMu AI free!
Conclusion
Pick one matrix your team already tests by hand, write it as a PICT model with its constraints, and run check-pairs.js on the output before trusting it. To run the rows in parallel, generate the session values in TestMu AI's Capabilities Generator and follow the Selenium with JavaScript guide to point the script from step 5 at your own account.
Tracking tests across tools and teams? TestMu AI's Test Manager keeps test cases, runs and results in one place.
Author
Abhishek Mishra
Blogs: 17

Abhishek Mishra is a Technical Product Manager at TestMu AI, where he owns Test Manager, the test management product. He has over 8 years of experience in product management and market analysis, spanning AI-native software testing, product strategy, and analytics. On TestMu AI, he authored guides on test management and test case management. Previously, he served as the Product Lead at IndiaClan and co-founded Gartley618 Technologies, a firm focused on quantitative trading and blockchain. He holds a B.Tech degree.
Reviewer
Himanshu Sheth
Reviewer
Himanshu Sheth is the Director of Marketing (Technical Content) at TestMu AI, with over 8 years of hands-on experience in Selenium, Cypress, and other test automation frameworks. He has authored more than 130 technical blogs for TestMu AI, covering software testing, automation strategy, and CI/CD. At TestMu AI, he leads the technical content efforts across blogs, YouTube, and social media, while closely collaborating with contributors to enhance content quality and product feedback loops. He has done his graduation with a B.E. in Computer Engineering from Mumbai University. Before TestMu AI, Himanshu led engineering teams in embedded software domains at companies like Samsung Research, Motorola, and NXP Semiconductors. He is a core member of DZone and has been a speaker at several unconferences focused on technical writing and software quality.


Pairwise Testing FAQs
Did you find this page helpful?
More Related Learning Hubs








TestMu AI forEnterprise
Get access to solutions built on Enterprise
grade security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests