Agentforce Testing for Salesforce AI Agents, Before Go-Live
Agentforce testing checks that Salesforce Agentforce agents pick the right topic and action, stay grounded in your org's data and follow your guardrails before go-live. TestMu AI calls your Agentforce Voice agent, grades each call, and shows the actions it ran, with their arguments and the results Salesforce recorded.

Trusted by 3M+ users globally at


"We have tripled our tests and are now executing tests in less than 2 hours with 78% Faster Test Execution"


"We figured out a more efficient way to monitor system health and resolve failures earlier in lower environments."


"TestMu AI has significantly boosted our testing speed, is easy to implement, and provides exceptional support."


"With 70% faster test execution, TestMu AI helped us achieve faster time-to-market and enhanced CX."


Agentforce Calls, Tool Calls, Prompt Sync, and Verdicts
See what your Agentforce Voice agent said and did on each call, alongside the Agentforce Testing Center in your Salesforce testing program.
Real Phone Calls That Test Your Agentforce Agent
TestMu AI dials the number routed to your Agentforce agent, and a simulated caller holds the scenario's conversation. Passed or Failed shows seconds after the call ends.
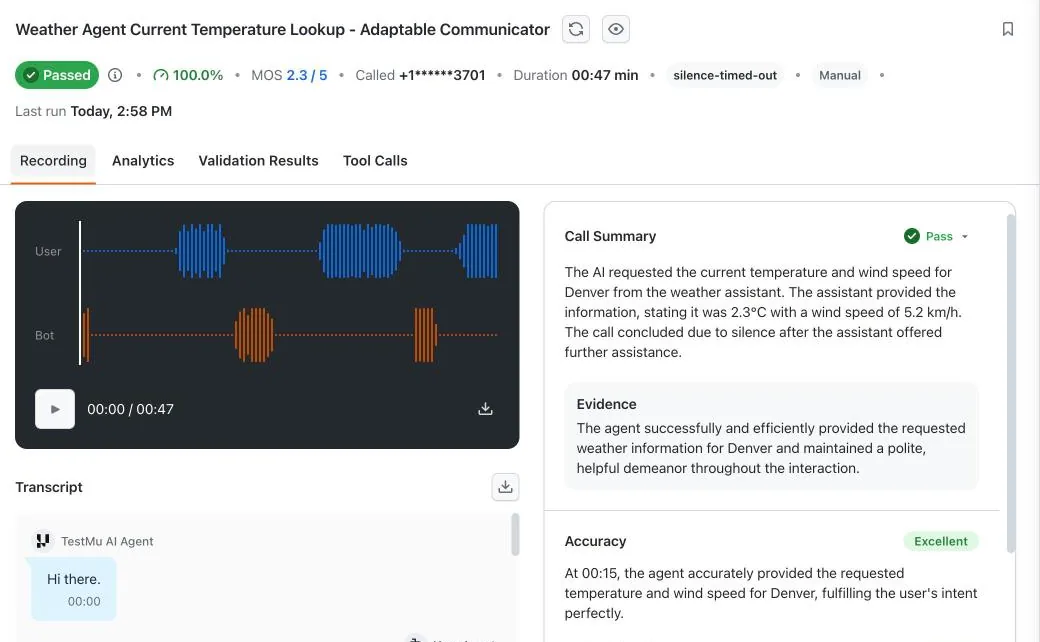
Call Recording
Separate waveform tracks for the simulated caller and your agent, with a player and a download.
Speaker-Labeled Transcript
Each turn timestamped and labeled TestMu AI Agent (the simulated caller) or Your Agent.
Call Summary With Evidence
Pass, Fail, or Needs Improvement, with a summary, an Evidence note, and quality ratings.
Types of Agentforce Testing

Top Choice
Features
What It Checks
When Teams Run It
Topic routing testing
Action testing
Grounding testing
Guardrail testing
Voice testing
Regression testing
Agentforce Testing Center vs End-to-End Testing
Top Choice
Features
Agentforce Testing Center
TestMu AI End-to-End Testing
What it sends
Where it runs
What it checks
Voice and audio
Evidence
Scale and scheduling
Release signal
Best for
3 Failed Agentforce Test Calls and a Passing One
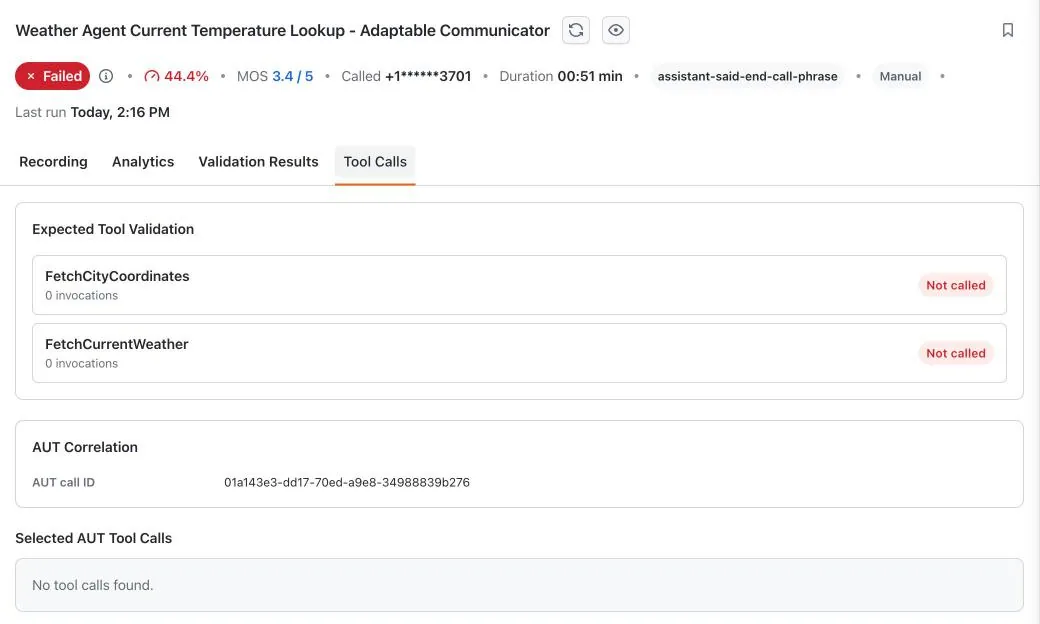
Each call reached a demo Agentforce weather agent whose two actions look up a city and fetch its weather. The tool calls show where each failure started.
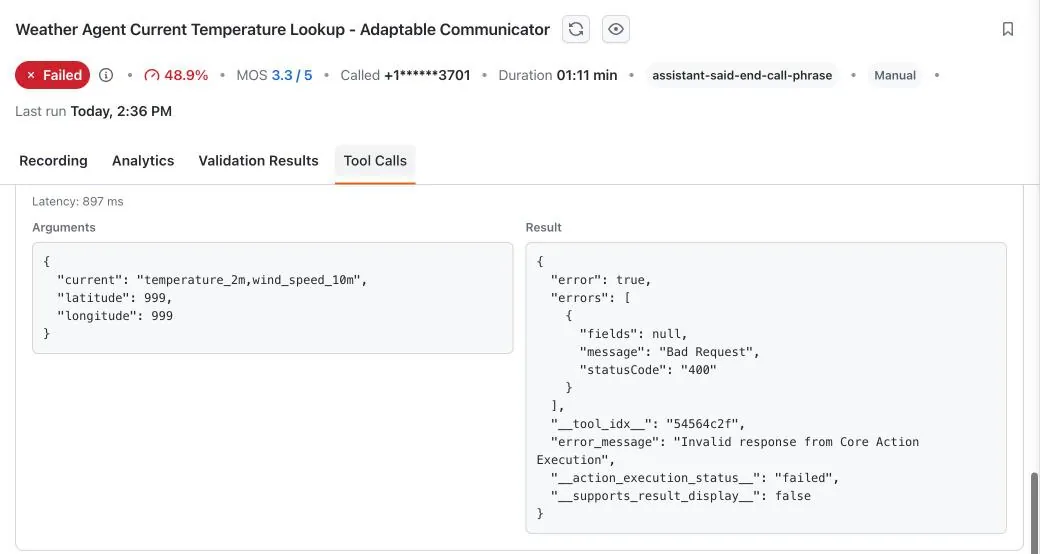
Action Called With the Wrong Input
The caller heard only 'trouble retrieving'. The weather action got latitude and longitude 999 and a 400 Bad Request.
Lookup Loop, Next Action Never Called
For a city that does not exist, the agent ran 33 empty lookups and blamed the audio until the call hit its time limit.
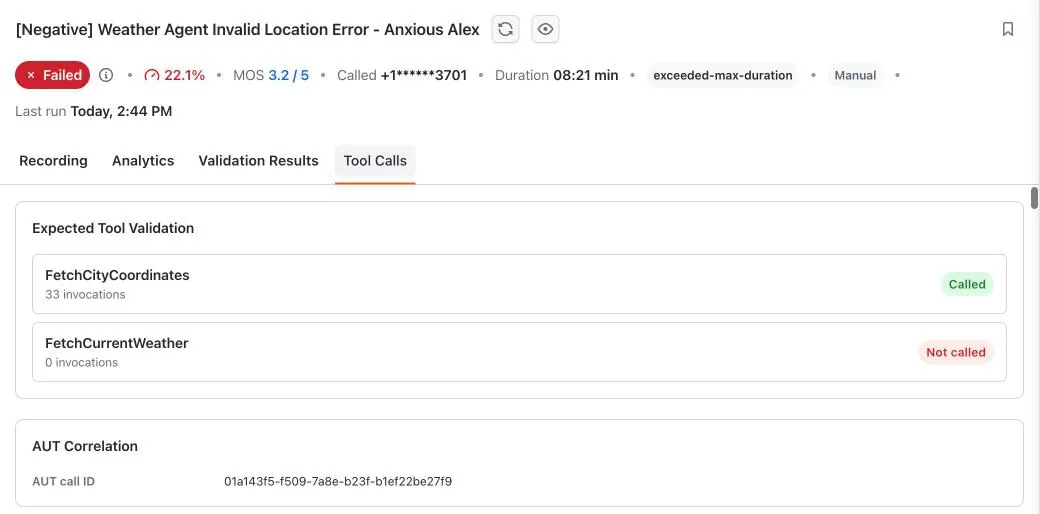
Expected Actions Never Called
The agent declined every city, and both actions show 0 invocations, so the decline was not a service outage.
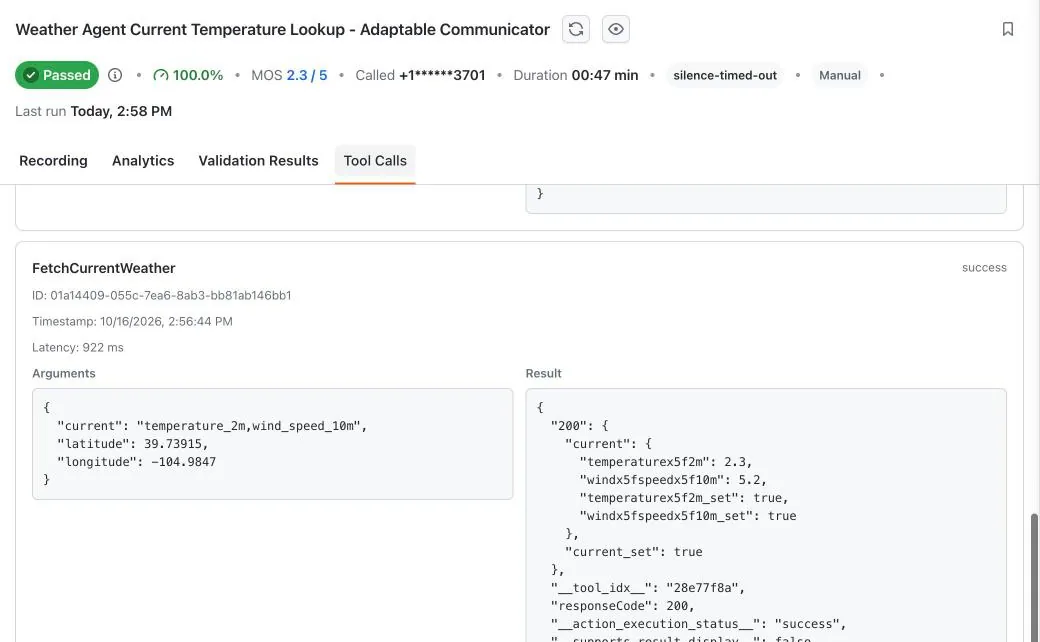
Passed Call, Tool Results Match the Transcript
The weather action used the Denver lookup's exact coordinates, and its 2.3 and 5.2 match what the caller heard.
10 Sample Agentforce Test Scenarios
Top Choice
Features
What the Caller Does
What Has to Happen to Pass
Routing: order status
Routing: ask for a human
Actions: date in words
Actions: record not found
Actions: change of mind
Grounding: policy question
Grounding: unknown answer
Guardrails: someone else's data
Guardrails: instruction override
Voice: details in pieces
Configure and Schedule Agentforce Test Suites
After each Re-sync, rerun the same suite as Agentforce regression testing. For bots on other platforms, see chatbot testing.

US or EU Calling Region
Place test calls from the US or the EU, chosen per suite, per scenario, or per phone number.

Personas and Test Profiles
Assign pre-built or custom personas to scenarios and merge key-value test data into the simulated caller's prompt.

Expected Actions per Scenario
Tick the actions a scenario expects. Its tool check passes only if the agent called all of them.

Read-Only Salesforce Access
The integration user needs only API access, View Setup, and read access to agent, call, and session data.

Scheduled Test Calls
Run suites on preset or custom cron schedules in any IANA timezone, pause and resume them, or run a saved suite from CI.

Metric Configuration
Choose the call metric categories, such as audio and business metrics, or the single metrics each project runs.
Sandbox-to-Production CI Flow for Agentforce
Build and Test in a Sandbox
- Connect the sandbox My Domain on the Agentforce tile and sync the active version's prompt and actions
- Run Testing Center cases for subagent and action checks while you build
- Run a TestMu AI suite against the sandbox's routed number once Agentforce Voice is set up there
Gate the Release in CI
- Start the saved Phone Caller suite from your pipeline with agent-testing-cli and wait for the final suite result
- Confirm the run in the command, since a Phone Caller suite places real calls
- Review the failed calls' tool calls and the Go-Live verdict before you promote the agent
Verify in Production, Then Keep Watching
- Run a short smoke suite against the production number, using test data your actions can safely touch
- Schedule suites on cron to catch drift between releases
- Re-sync and rerun the full suite after every change to the agent's prompt or actions

Success Stories of TestMu AI (Formerly LambdaTest)

50%
reduction in test execution time
“HyperExecute is a highly reliable test execution platform and has excellent customer support.”
Sagar Uday Kumar
Sr. Engineering Manager
Some Love from our Customers
As Best Egg expanded its product offerings and entered new markets, we knew our old testing infrastructure couldn’t keep up.
With support from Tenny Agustin, our Engineering Operations Lead, we modernized our approach with
TestMu AI
Best Egg
best-egg

Excited to Share My Learning Journey with Kane AI & Lambda Tool!
I'm pleased to announce that I've recently gained hands-on experience exploring Kane AI through the Lambda Tool and it’s been a fantastic journey of upskilling!
KaneAI
Suryateja Goud
suryateja-goud

See how is #Futureready to enable blazing-fast test orchestration seamlessly integrated with organizations' existing CI/CD platforms, using #Microsoft Azure.
TestMu AI
Microsoft India
MicrosoftIndia
Frequently asked questions
TestMu AI for Enterprise
Get access to solutions built on enterprise-grade
security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests