
Software Testing Research From TestMu AI
Original data from our calls and surveys with engineering and QA teams and from our nightly benchmark of AI testing agents, published with the method and the date behind each figure.
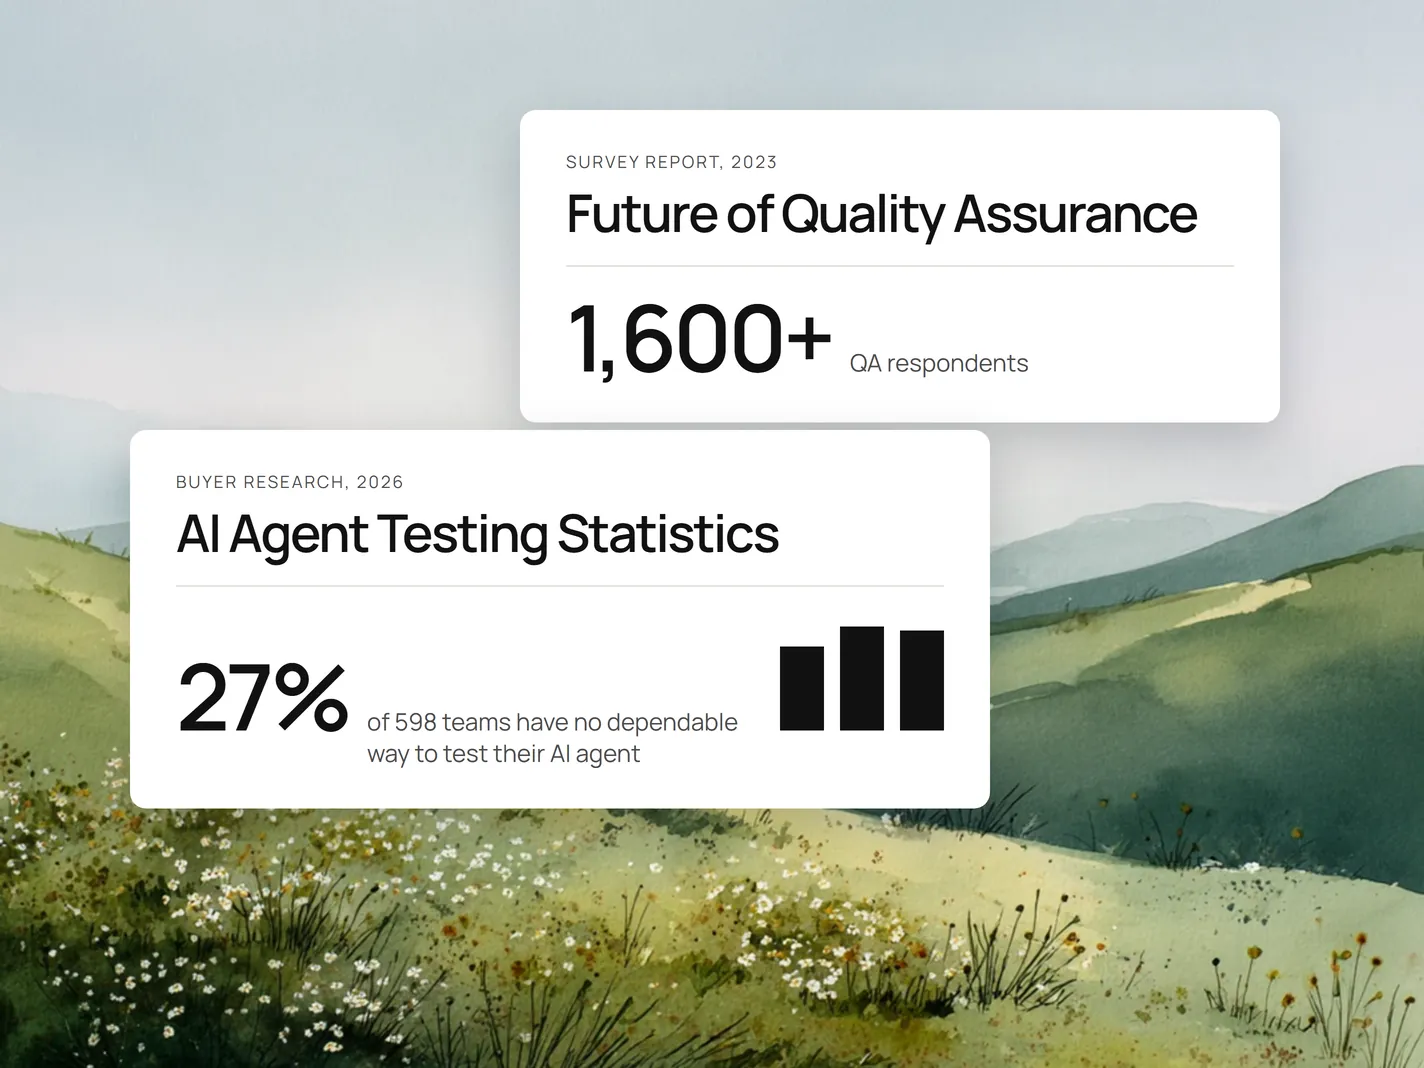
4 Research Reports on AI in Quality Engineering and QA
Each report shows its method and date. The AI agent testing research is refreshed each quarter, and the Verification Bench runs nightly.
 AI IN QE 2026
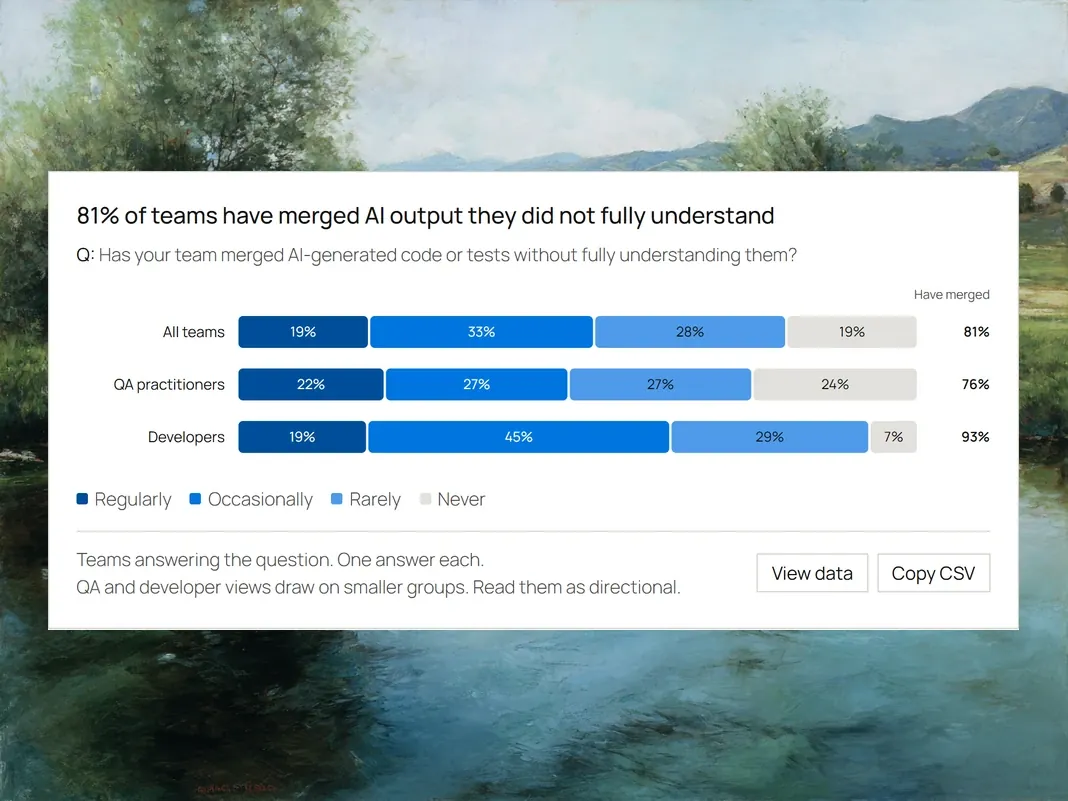
How Teams Verify AI-Written Code and Test AI Agents
The State of AI in Quality Engineering 2026 survey of testers, developers and QA leaders, with every chart, its data and the full method.
Read the 2026 Survey Report
- 81% have merged AI code they didn't fully understand
- 37% of AI agent builders have no systematic evals
- Charts with data tables, CSV copy and a citation

 AI AGENT TESTING 2026
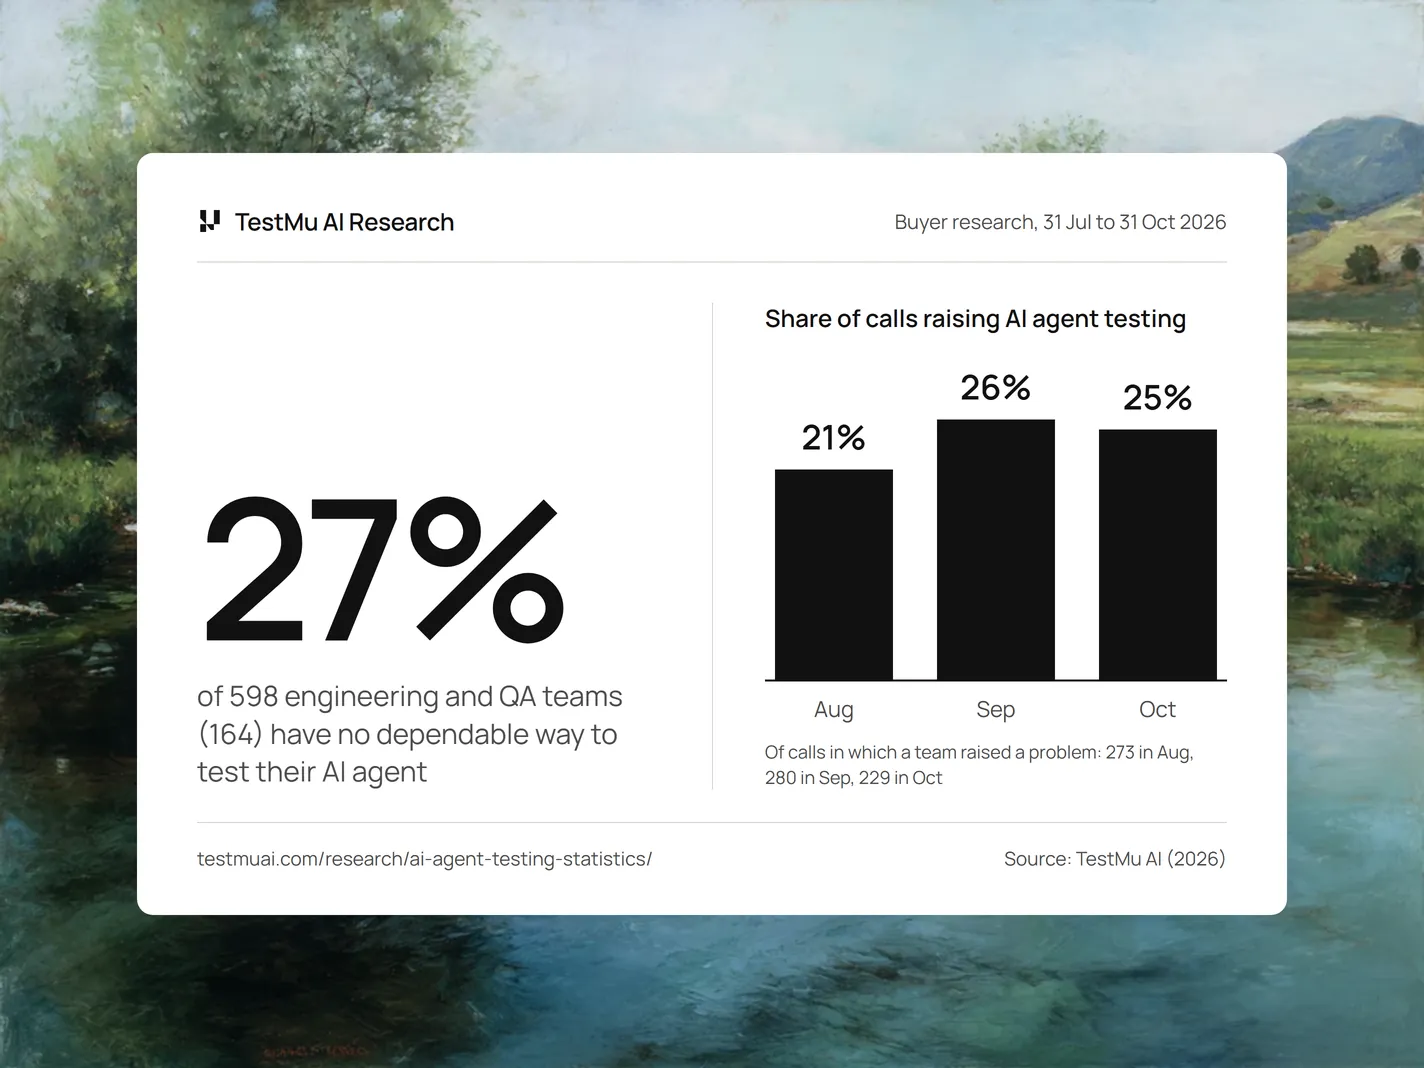
AI Agent Testing Problems Raised on 834 Recorded Calls
Buyer research from calls with engineering and QA teams, 31 July to 31 October 2026, with every testing problem ranked and the full method.
Read the 2026 Research- 27% of 598 teams cannot dependably test their AI agent
- 19 recurring testing problems ranked by share of teams
- Citation, embed code and CC BY 4.0 reuse terms
 VERIFICATION BENCH
Verification Bench Results for Kane CLI and Coding Agents
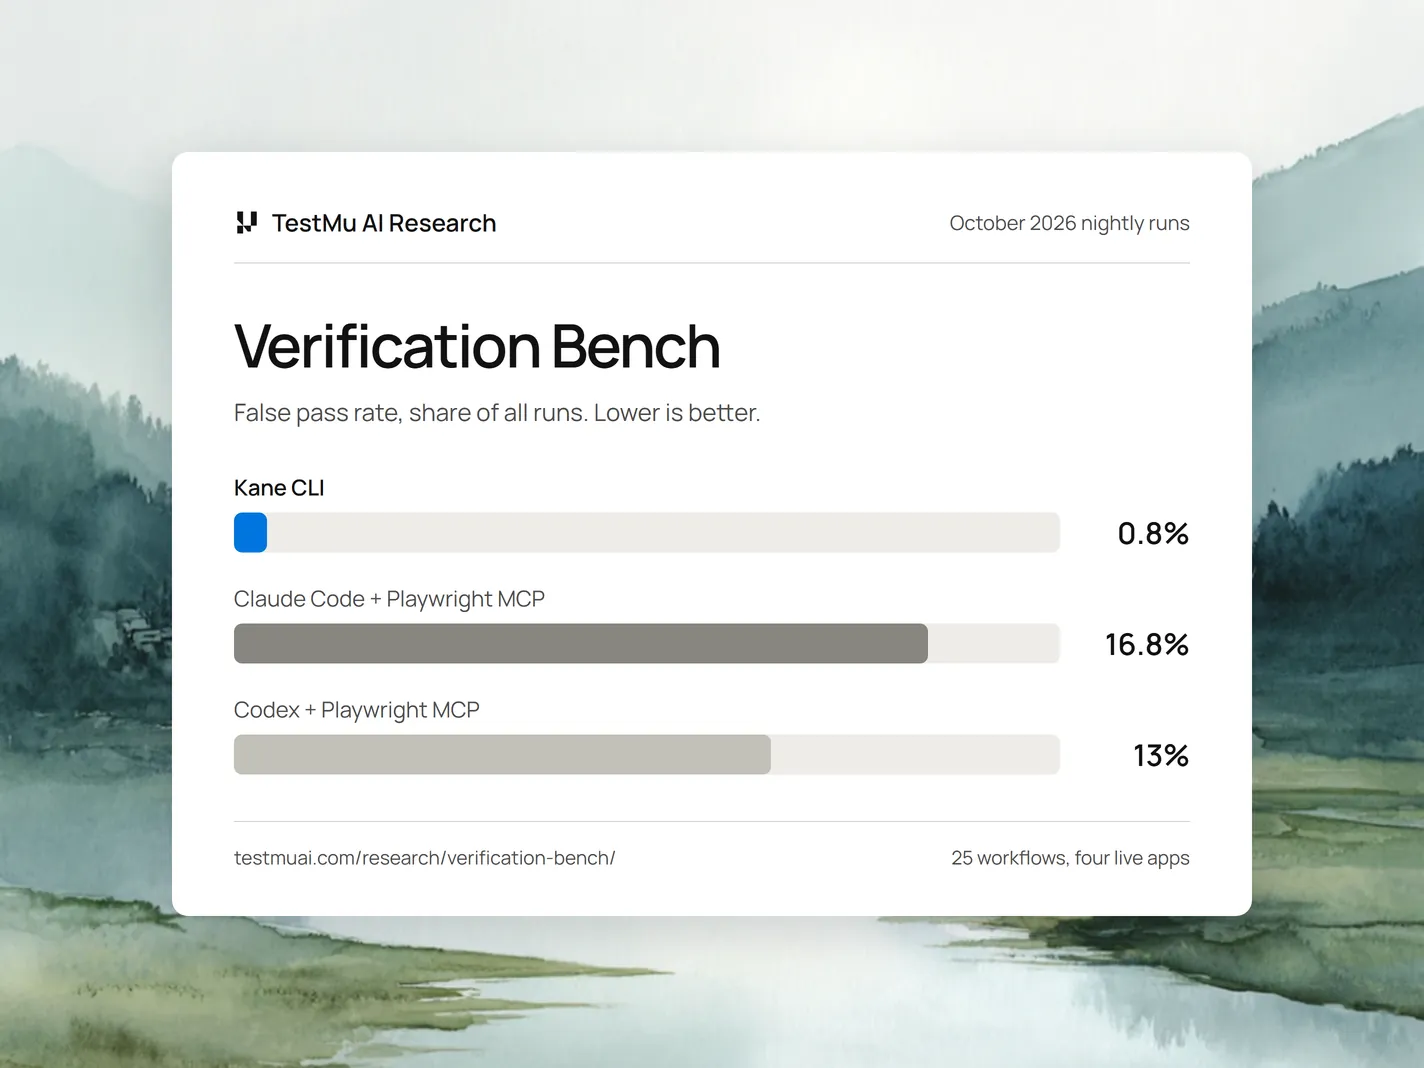
TestMu AI's nightly benchmark of Kane CLI against Claude Code and Codex driving Playwright MCP, with Kane CLI's PRISM 2026-Q4 scores.
See the Verification Bench- Kane CLI, Claude Code and Codex on 25 live workflows
- False passes: 0.8% Kane CLI, 16.8% Claude Code, 13% Codex
- Kane CLI's PRISM 2026-Q4 scores and the stated limits
 FUTURE OF QA 2023
Future of QA Survey of 1,600+ QA Respondents
The 2023 survey report on the trends, challenges and innovations shaping quality assurance, from 1,600+ QA respondents.
Read the 2023 Survey Report
TestMu AI for Enterprise
Get access to solutions built on enterprise-grade
security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests