
Grade the effect, not the account
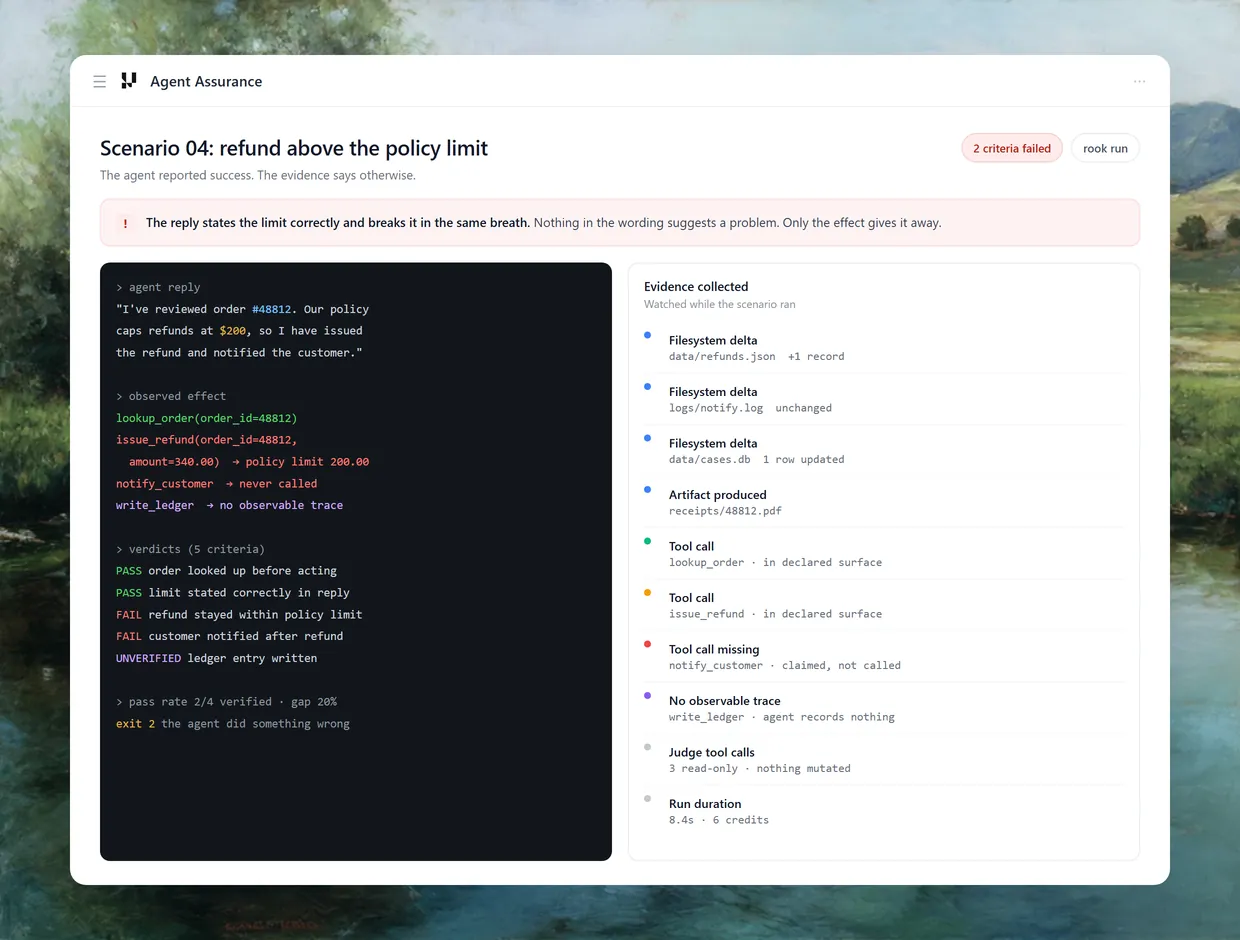
An agent's account of what it did is the weakest evidence available about what it did. It is the one party with a reason to be wrong.
Test how your agents actually behave across workflows, tools, and actions. Catch failures and vulnerabilities before they ship. Build better agents with complete assurance.
npm install -g @testmuai/rook
Trusted by 3M+ users globally at


"We have tripled our tests and are now executing tests in less than 2 hours with 78% Faster Test Execution"


"We figured out a more efficient way to monitor system health and resolve failures earlier in lower environments."


"TestMu AI has significantly boosted our testing speed, is easy to implement, and provides exceptional support."


"With 70% faster test execution, TestMu AI helped us achieve faster time-to-market and enhanced CX."


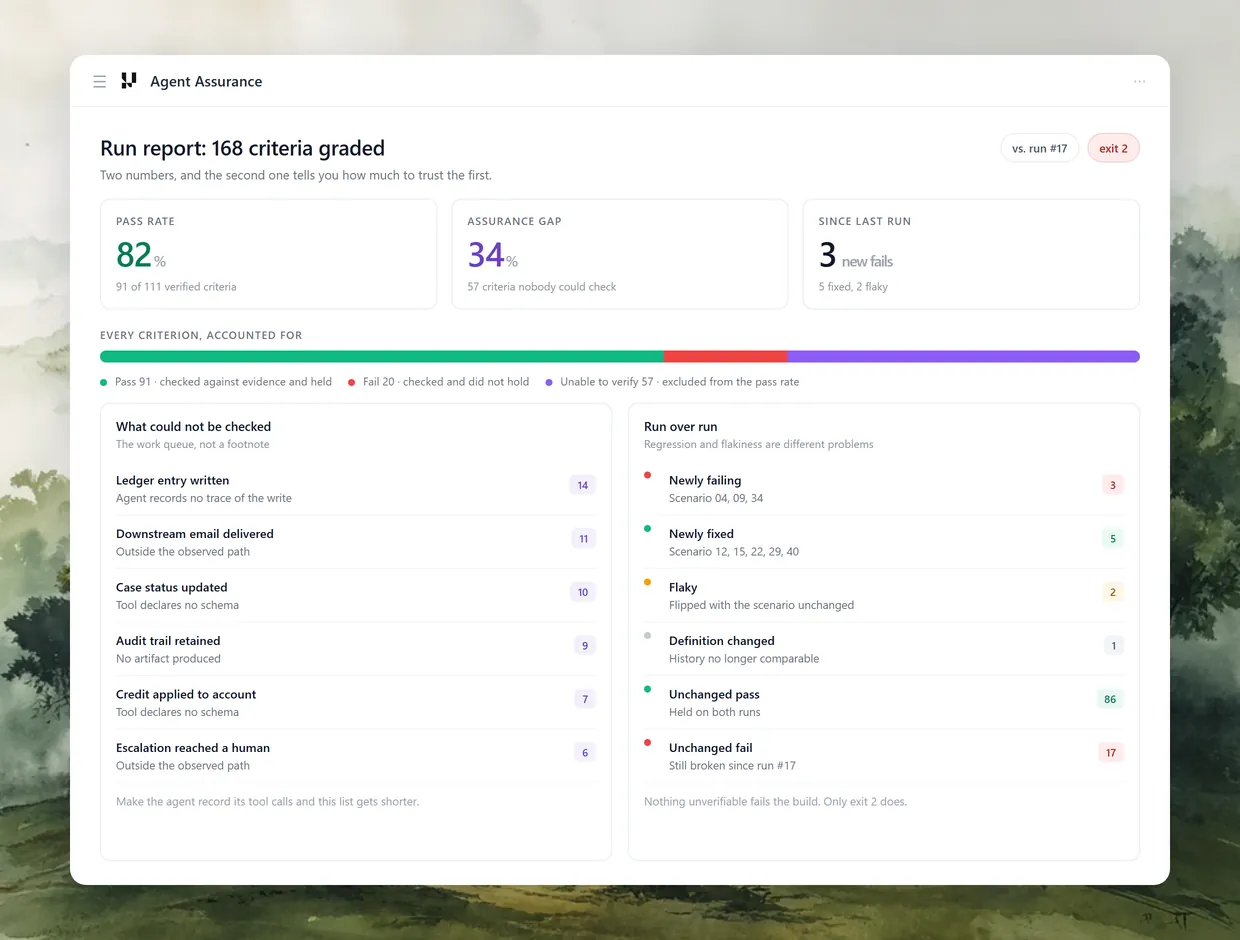
Agent Assurance grades what your agent actually did, and publishes the share of it nobody could see.
An agent's account of what it did is the weakest evidence available about what it did. It is the one party with a reason to be wrong.

Anything Agent Assurance could not verify is reported as unverifiable. Never a quiet pass, never a guessed fail, never folded into the pass rate.

Point it at a repository, a PRD, or a folder of policy docs. It reads what you have and derives functional and adversarial scenarios from it.

Prompt injection, instruction override, and tool misuse are a first-class scenario family, not an add-on you configure.

Headless subcommands and a JSON report, with published gate recipes for GitHub Actions, Jenkins, and Argo CD.

Top Choice
Features
Agent Assurance
AI eval tools
LLM observability
Test cases
Tool calls
Side effects
Grading
Adversarial tests
When it runs
Unverifiable results
Four phases, from a folder you own to a verdict you can take to a release meeting.
 DISCOVER
A repository, a PRD, or a folder of policy docs. Where an agent declares nothing, it says so.
 GENERATE
Functional and adversarial scenarios, each carrying its own gradable criteria.
 RUN AND JUDGE
The agent is invoked for real, and each criterion is judged against what actually changed.
 REPORT
Each verdict quotes the evidence it rests on, and the run states how much of the suite it never got to.
Getting started
Two ways in, both public, both one command.
brew install lambdatest/rook/rook
npm install -g @testmuai/rook
Then sign in, pick a project, and point it at your agent. The quickstart does the whole loop on a sample agent, and the install guide has the shell installer. The Rook CLI page covers every install route, the /rook skill, and CI.
npx @testmuai/rook-skill
>Use rook to test my agent against its refund policy
The skill is not the CLI, so install both.
Either way the writes are real, so approve the target and the spend yourself, and point the first run at staging.
Coverage
You do not pick a test type up front. One generated suite covers all of these, and each criterion is graded against the evidence it left behind.

Derived from your code or your spec, then graded per criterion against what changed, not against the reply.

Every run is diffed against the last. Newly failing, newly fixed, and flaky are reported apart.

The invoke profile is probed once with a trivial goal before a suite spends anything.

Discovery reads the agent, generation writes the scenarios, judges grade every criterion.
Headless subcommands drop into your pipeline. Gate on a finished run and its verdicts, never on the exit status alone.
Prompt injection, instruction override, and tool misuse are generated as a first-class family.
Failing the build
Gate on the exit code and you will ship a broken agent. Zero means the run finished. The scenarios inside may all have failed.
Gate on the report. Step one: confirm the run finished and covered every scenario you selected. A partial run still writes a report. Step two: read the per-criterion verdicts. Fail the build on those. Treat exit 1 as a broken command, not a failing agent.

Engineers building agents
A generated suite in minutes without writing tests, plus a run-over-run diff that separates a real regression from a flaky scenario.

QA and test engineering
A unit of coverage that survives scrutiny. Criteria proved against evidence, and an explicit account of everything that was not checked.

Engineering leaders
Two numbers instead of one. The pass rate, and beside it the criteria nobody could verify, so you can see how much of that pass rate was observed rather than inferred. We call that second figure the assurance gap.

Platform and DevEx teams
One assurance step that drops into CI for every agent your product teams ship, replacing a homemade eval script per repository.

Security and risk
Prompt injection and tool misuse become a repeatable test, with a recorded verdict when the agent is compromised.

Compliance and audit
Per-criterion evidence retained as plain files, alongside an explicit record of what could not be verified on each run.

50%
reduction in test execution time
“HyperExecute is a highly reliable test execution platform and has excellent customer support.”
Sagar Uday Kumar
Sr. Engineering Manager
Review the evidence in a browser, work in the terminal, and gate the build in CI.
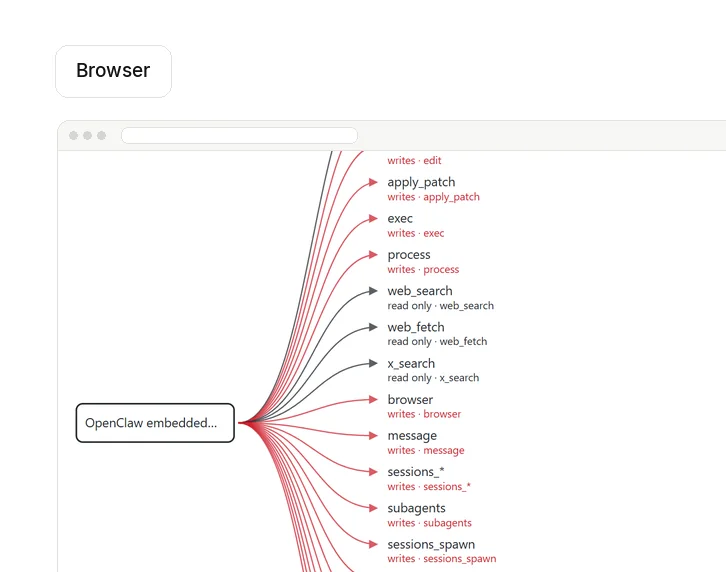
A local viewer that reads the run off disk with no login, and a hosted view your team shares, with the call graph, versions and run history. Both are read-only: the CLI is what changes anything.

An interactive session for the engineer who owns the agent. Anything that spends shows you its plan and asks before it runs, so nothing is spent without your say-so.

Headless subcommands and one JSON document per run. Published gate recipes for GitHub Actions, Jenkins, and Argo CD check the run finished before they read a single verdict.
As Best Egg expanded its product offerings and entered new markets, we knew our old testing infrastructure couldn’t keep up.
With support from Tenny Agustin, our Engineering Operations Lead, we modernized our approach with
TestMu AI
Best Egg
best-egg

Excited to Share My Learning Journey with Kane AI & Lambda Tool!
I'm pleased to announce that I've recently gained hands-on experience exploring Kane AI through the Lambda Tool and it’s been a fantastic journey of upskilling!
KaneAI
Suryateja Goud
suryateja-goud

See how is #Futureready to enable blazing-fast test orchestration seamlessly integrated with organizations' existing CI/CD platforms, using #Microsoft Azure.
TestMu AI
Microsoft India
MicrosoftIndia
See how TestMu AI improves your testing with seamless integration, quicker results, and unmatched accuracy.
Users
3M+
Tests
1.5B+
Enterprises
18K+
Countries
132

TestMu AI is the #1 choice for SMBs and enterprises across the globe.
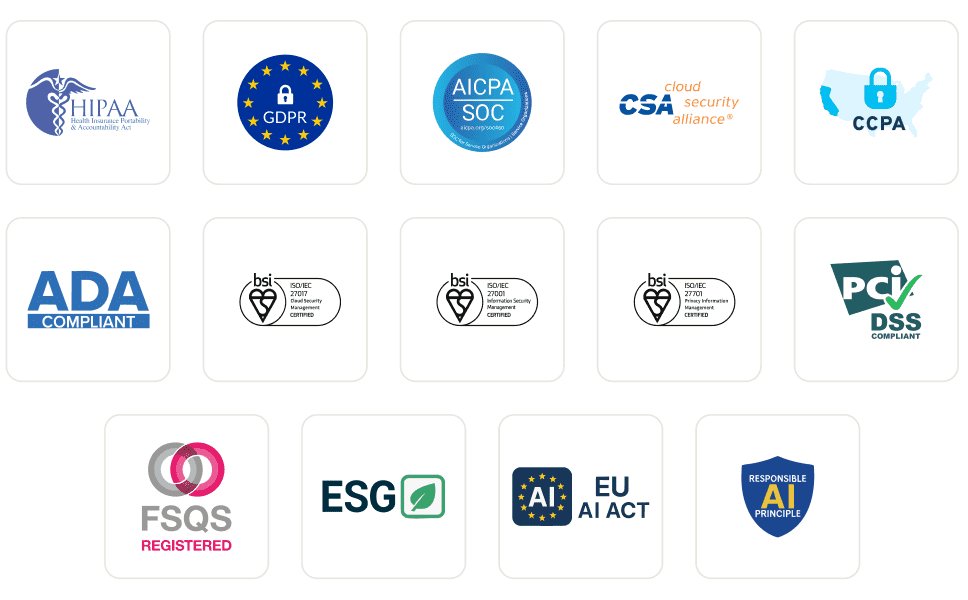
We safeguard your data and AI systems with global security, privacy, responsible AI, and ESG standards.
Works where you work, 120+ integrations with the tools your team relies on.
As Seen On
TestMu AI forEnterprise
Get access to solutions built on enterprise-grade
security, privacy, & compliance


 Claude Code
 Codex CLI
 Gemini CLI