

Power Your Software Testing with AI Agents and Cloud
The Native AI-Agentic Cloud Platform to Supercharge Quality Engineering. Test Intelligently and Ship Faster.


- TestMu AI (Formerly LambdaTest)
- /
- Blog
- /
- How Large Language Models Are Revolutionizing Software Testing- Part 1
AI-Powered QA: How Large Language Models Are Revolutionizing Software Testing- Part 1
Large language models now write tests, draft bug reports, and update test documentation. Learn where they help software testing and where they break.
Last Updated on:
On This Page
- Tokens: The Lego Bricks of How LLMs Think About Testing
- Speed vs. Quality
- Breaking Points of Traditional Testing
- Framework Evolution: Keeping Up with Moving Targets
- Documentation Drift: Falling Behind
- The Consequences of Maintenance Overhead
- Coverage Gaps: The Known Unknowns
- Resource Constraints: The QA Bottleneck
- AI Testing Agents
Large language models (LLMs) are revolutionizing software testing by generating tests, test data and documentation from code and plain-language requirements. They read code as tokens, so the same model that writes a function can also write its test and explain why that test failed.
This guide covers how tokens shape LLM testing, the speed versus quality trade-off, where traditional testing breaks (framework evolution, documentation drift, maintenance overhead, coverage gaps and resource constraints) and how AI testing agents address those breaking points.
Key Takeaways
- Large language models read code, text, video and other digital inputs as tokens, so the same model that understands a function can also write the test for that function.
- UI tests break on small changes such as a login button id renamed from login-button to btn-login, which sends QA time into repair work instead of new coverage.
- Test data decays when database schemas change, when test accounts expire under password aging policies, or when dynamic sources such as product catalogs move on.
- Documentation drift sets in when test steps are updated without touching the test case description, leaving new team members to rely on tribal knowledge during onboarding.
- Coverage gaps widen with feature complexity, third-party integration counts, unpredictable real user flows, and mobile fragmentation across device models, OS versions and screen sizes.
- AI testing agents heal locators by role, label or visible text, generate synthetic data that matches the current database schema, and write test case descriptions from the test code.
- KaneAI from TestMu AI is an end-to-end software testing agent built on large language models, aimed at testers who need to keep pace with release speed without extra manual work.
- A healed locator can point at the wrong element and a generated test can pass against a bug, so a tester reviews every agent output before the test merges.
Tokens: The Lego Bricks of How LLMs Think About Testing
I’ll do my best to keep this short. There is a lot of hype around AI / LLMs but many people do not have an understanding of how it actually works. I hope you’ll forgive my oversimplification of it in this section, but I think it is necessary to start with some basics.
Think of tokens as individual pieces of a puzzle that a computer (LLM) uses to understand what it’s looking at. When we use LLMs for testing, these “tokens” could be a word, part of a word, a piece of code or even a special character like a comma. Each token is one tiny bit of information the LLM needs to assemble to get the whole picture.
Consider this small piece of code for a test:
def test_login():
The LLM would look at this and break it down into smaller parts or “tokens” like:
- def (tells the computer a function is starting),
- test (the function’s name),
- _ (a small character that separates words),
- login (what the function is testing for),
And so on.
Each of these tokens helps the LLM understand what it’s supposed to do. By assembling these pieces the LLM starts to “understand” the code, almost like a person reading a sentence. It uses that understanding to create tests, check for errors and make sure the code works as expected. So when we talk about LLMs creating tests we’re really talking about how they look at each token and use them like puzzle pieces to get the whole picture.
This is where prompt engineering helps, by getting the engines to use a different context to solve the puzzle and assemble the pieces differently, but more on that later in a different blog.
We’ve moved beyond simple text processing; today’s technology can interpret text, videos, voices, and more. At its core, anything that can be saved in a digital format is readable, can be broken down into tokens, and therefore falls within what LLMs can understand. This token-based structure makes LLMs powerful tools for interpreting and acting on various types of data, whether it’s code, complex documents, or multimedia, opening up exciting possibilities for future applications across different fields.
Speed vs. Quality
AI is already writing a lot of code and that will only get faster.
Companies need to deliver software fast, or be eaten by competition. But at the same time, companies also need to show stable solutions. This is where the traditional testing approach forces an impossible trade-off: slow down releases or accept higher risk.
Neither option is acceptable in today’s world.
Breaking Points of Traditional Testing
Let’s look at a few scenarios where the traditional test approaches have no answer (yet)!
Fragile Tests: Breaking with the Tiniest Change
UI tests are notorious for being brittle. Renaming a button, changing a layout, or modifying an attribute can break hundreds of tests even though the underlying functionality remains intact.
For example, a Selenium test might break if a developer changes the id of a login button from “login-button” to “btn-login”. Without self-healing capabilities or smart locators, your QA team is stuck updating test steps for every minor UI change.
But it gets worse. With AI-powered test code generation, the amount of new code can overwhelm even the most robust automation frameworks. No tool on the market can keep up with the volume and pace of changes in today’s software without significant manual configuration.
Even if some of the automation frameworks manage to keep up, it is only a (very short) matter of time before the volume of new code overwhelms them.
Test Data Decay: Resetting Your Testing Foundation
Your automated tests are only as good as the data they rely on. Test data can decay, become invalid, or drift away from your app’s new requirements:
- Database Schema Changes: Modifications to database structures make existing test data invalid or unreadable.
- Expired Test Accounts: Test user accounts lock or expire due to password aging policies or changes to production data.
- Dynamic Data: Apps that rely on constantly changing data, such as product catalogs or user profiles, require refreshed test data to stay relevant.
Resetting your testing foundation is no easy task. It requires hours, if not days, of manual effort to update, clean, or regenerate test data.
Every experienced tester will know exactly how the quality of test data directly impacts the ‘quality’ of ‘Quality Assurance’. Testing would be so much easier & testers would be far more productive if only test data was always top-notch!
Modern Generative AI tools are beginning to address this gap by synthesizing realistic test data on demand, reducing the manual overhead of keeping test datasets current and aligned with evolving application state.
Framework Evolution: Keeping Up with Moving Targets
Automation frameworks, libraries, and tools are rapidly evolving to fit modern DevOps practices. But with each new release comes the problem of:
- Backward Compatibility: Framework updates often deprecate methods or introduce breaking changes that break older test scripts.
- Learning New Features: Your QA engineers need time to learn new updates, which can delay your testing timeline.
- Refactoring Test Suites: You may need to re-architect entire test suites to take advantage of new framework features.
Documentation Drift: Falling Behind
Test documentation provides valuable context for test cases, but it often struggles to keep up with the pace of development. Documentation drift happens when:
- Test steps are updated without touching the test case description or documentation.
- Developers and QA teams forget to sync docs with the latest app changes.
- Teams rely on ad-hoc notes or tribal knowledge instead of centralized, up-to-date documentation.
The result? Confusion, duplicated effort, and a long onboarding process for new team members.
I know, that with the advent of agile methodologies, documentation is getting out of fashion. However, try telling that to your Ops teams who struggle to understand how a feature was built & tested when trying to answer a complex customer question.
The Consequences of Maintenance Overhead
QA teams often spend a significant part of their time maintaining existing tests instead of focusing on important tasks like exploratory testing, performance testing, or creating new test cases. This resource drain leads to:
- Stagnant Test Coverage: Time spent on maintenance leaves little room to expand test coverage to new features or risk areas.
- Accumulated Technical Debt: Ignored maintenance builds up over time, requiring more aggressive fixes down the road.
- Team Burnout: The never-ending battle to keep tests passing can lead to QA team burnout and frustration.
On a side note, Amy has a few practical tips on AI-powered test maintenance.
Coverage Gaps: The Known Unknowns
Despite all the progress we’ve made in automation and testing frameworks, coverage gaps remain one of the biggest challenges for QA teams. These “known unknowns” are the silent killers that allow bugs to slip through and degrade the user experience. In extreme cases, they can even cause catastrophic failures in production. The ‘unknown unknowns’ will become an even more intense problem with the rise of AI-generated code, but that is a blog of its own.
Edge Cases: Testing the Unpredictable
Modern applications are complex. We can’t possibly anticipate and test for every possible scenario. Let’s talk about some of the challenges QA communities face:
- Feature Complexity: Every new feature adds more edge cases. As the system grows, so does the number of possible combinations. For example, a simple discount feature in an e-commerce app can have hundreds of edge cases when you combine it with user types, product categories, and payment methods.
- AI-Generated Agents: Bots are becoming popular as B2C and B2B customers. Their behavior is unpredictable and exposes system behaviors we never would have imagined. They can also exploit system weaknesses much faster than any human.
This shift toward autonomous interactions aligns with concepts discussed in MCP and AI Agents, where intelligent agents interact with systems and tools while maintaining contextual awareness across workflows.
Integration Points: The Math Problem
Our modern application ecosystems are increasingly made up of multiple APIs, microservices, and 3rd party integrations. This creates a staggering number of possible touchpoints.
- Service Dependencies: A dependent API or unexpected response format can break critical user journeys.
- Chained Interactions: When multiple services are involved, a failing component can cause unpredictable errors throughout the app.
- Dynamic Environments: Changes to external services or dependent systems can introduce hard-to-reproduce bugs.
We can’t mathematically test for every possible combination, so we prioritize and hope we don’t miss the critical gaps. Risk-based testing was not ideal, but it was our only option as QA professionals so (far).
User Flows: The Creativity of Real Users
In reality, users don’t navigate apps as we test them. They take shortcuts and use workarounds that our structured testing often misses.
- Unexpected Behavior: Users skip optional steps, enter edge-case data, and combine features in ways we never thought possible.
- Exploratory Navigation: A user may complete a step that triggers a rare bug in a complex workflow system. For example, a simple mobile baking app that has 10 main flows might have thousands of permutations in terms of how it might be used and categorically lies outside of any manual testing/manually coded automated tests.
- Cultural Differences: The global user base has different expectations and habits. Demographics, wealth, internet speed, etc., vary from country to country and reflect user behavior.
Mobile Variations: The Fragmentation Nightmare
We all know about the mobile fragmentation nightmare:
- Device Proliferation: Hundreds of device models with varying hardware and OS combinations create an exponential increase in testing requirements.This becomes particularly important in solutions that are primarily targeted towards the mobile platforms.
- OS Fragmentation: Various OS versions and custom skins lead to inconsistent behavior.
- Screen Sizes and Resolutions: UI and UX elements don’t render or function correctly on smaller or odd-sized screens.
Tip: Almost no organization can scale itself up to test everything that is possible. Using a test specialist increases your chances of staying on par with the speed of change.
Key Takeaway: Coverage gaps come from four directions at once: edge cases multiply as features combine with user types, product categories and payment methods; APIs, microservices and third-party services create more touchpoints than any suite can cover; real users take shortcuts and cultural habits that structured tests never model; and mobile hardware, OS versions and screen sizes fragment every check. Risk-based prioritization narrows the gap but cannot close it.
Resource Constraints: The QA Bottleneck
Our QA teams are overwhelmed and expected to do more with less. These are some of the biggest contributors to coverage gaps:
Tester Shortage: The Talent Deficit
We don’t have enough qualified test automation engineers. In fact, it’s one of the biggest challenges we face as an industry.
- Specialized Skills Required: Today’s QA teams need scripting skills, knowledge of automation frameworks, and DevOps practices. Now we’re adding AI-based tools to the menu.
- Burnout Risk: Our existing testers are stretched too thin and are at risk of burning out. They also lose focus and fail to take advantage of new approaches and techniques.
Infrastructure Costs: Testing on a Budget
Even with cloud solutions, maintaining proper test environment infrastructure can be expensive:
- Scalable Test Environments: Creating a realistic production-like environment at scale is costly (cloud resources, load testing tools, and network configs). While the infrastructure maintenance complexity has been outsourced to the cloud providers, the cost story hasn’t been exactly rosy!
- Tool Licensing: Many of the cool new AI-based testing tools are subscription-based and very expensive. Justifying the cost is a challenge for most teams. Most of the companies that offer an AI solution base the pricing on tokens. The longer your context window and the lengthier your prompts, the more it costs.
Cloud solutions were cool when they started. Newbie companies embraced it immediately, the larger & more established companies (that are typically regulated) came on board later. Cloud is now the norm, not for cost but for convenience! Many organizations while have some sort of cloud adoption, cost (& skill) is still a formidable challenge.
Time Pressure: Racing Against the Clock
Our Agile and DevOps cycles are getting shorter, and our QA teams are struggling with:
- Insufficient Testing Windows: Not enough time to run our full test suites before each release. We have covered this at length earlier. Saying no more!
- Expanded Scope: As our systems grow more complex, we need to test more than ever, but there’s not enough time to do it. As above, saying no more, again!
Our testing tools and methodologies also evolve at a faster pace than ever before:
- Emerging Technologies: From AI tools to new programming languages and frameworks, testers need to learn new skills quickly.
- On-the-Job Learning: Training often falls to on-the-job trial and error, which slows down the project and increases the strain on our already-stretched QA resources.
This is one of the most important topics for test professionals: keeping up with the pace of technology growth. With solutions like TestMu AI Kane AI, testers now have the opportunity to keep pace while reducing manual burdens, letting them focus on delivering quality at scale. World’s first end-to-end software testing agent, KaneAI by TestMu AI is an AI Native QA Agent-as-a-Service platform built on modern Large Language Models (LLMs)
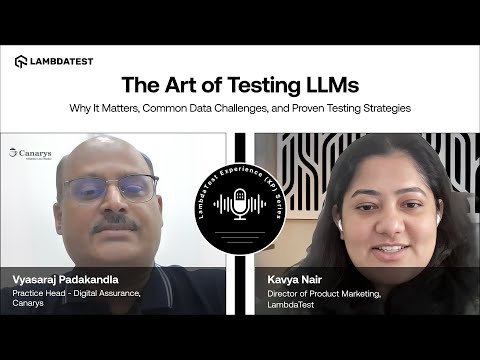
KaneAI is just one of the examples of how AI is transforming software testing. In the 2nd next part of the blog series, we’l explore how LLMs and AI is transforming the testing landscape.
Key Takeaway: The QA bottleneck has three sources: too few engineers who combine scripting, automation framework and DevOps skills, infrastructure and AI tool licensing costs that scale with token usage and production-like environments, and release cycles too short to run a full suite or to learn a new tool properly. Each one narrows what a team can test before a release ships.
How Do AI Testing Agents Address These Breaking Points?
AI testing agents address fragile tests, test data decay, documentation drift and coverage gaps by reading the application and the test code, then generating or repairing tests for a tester to review. The main approaches in use:
- Self-healing locators: When a login button id changes from login-button to btn-login, an agent finds the element again by its role, label or visible text instead of failing the run.
- Browser control through MCP: The Model Context Protocol (MCP) gives an LLM a standard way to call external tools. The Playwright MCP server uses MCP to let an agent open pages, click elements and read the accessibility tree of a page.
- Planner, generator and healer: Playwright Test Agents split the work in three. The planner explores the app and writes a Markdown test plan, the generator turns that plan into Playwright tests and the healer repairs failing tests.
- Mutation-guided test generation: At Meta, the Automated Compliance Hardening (ACH) tool uses an LLM to inject realistic faults into code, then generates tests that catch those faults.
- Synthetic test data: An LLM generates records that match the current database schema, which cuts the manual work of rebuilding test data after a schema change.
- Generated test documentation: An agent writes the test case description from the test code, so the description changes whenever the steps change.
Agents do not remove the need for a tester. A healer can point a locator at the wrong element, and a generated test can pass against a bug. Review every healed locator and generated test before merging, and budget for token costs, which grow with the context window.
TestMu AI ships these AI app testing capabilities as KaneAI, where a test is authored from a plain-English prompt, a Jira ticket or a screen recording, smart element detection re-anchors steps when the UI shifts, and the finished test exports to Selenium, Playwright, Cypress or Appium. Self-healing reduces maintenance rather than removing it, so every heal surfaces for a tester to approve.
Author
Chaitanya Sharma
Blogs: 18

Chaitanya Sharma is an AI Product Manager at TestMu AI (formerly LambdaTest), where he builds agentic AI capabilities focused on computer vision and multi-modality, moving testing beyond static script execution toward autonomous, agent-driven workflows. Before TestMu AI he shipped 135+ features at Sprinklr for a no-code community and website builder used by Fortune 500 enterprises including Dell, Samsung, and Polestar. At Policybazaar he led the zero-to-one launch of a digital lending and insurance marketplace embedded in Bahrain's dominant payments app, building a risk-intelligence engine that compressed loan-approval times by 80%. He explored machine learning and NLP through research at the University of Cambridge, and holds a B.Tech from Delhi Technological University.
Reviewer
Anubhav Singhmaar
Reviewer
Anubhav Singhmaar is an AI Product Manager at TestMu AI driving Kane CLI, the command-line tool that brings browser automation to the terminal, turning natural-language flows into runs in a real Chrome browser that return pass or fail with shareable proof. He owns the roadmap and prioritization and works with engineering to ship developer-facing features. Before TestMu AI, he spent over four years at Sprinklr owning enterprise voice AI across APAC and EMEA. A mechanical engineer turned product manager, he grounds guidance in real QA workflows.


LLMs in Software Testing FAQs
Did you find this page helpful?
More Related Blogs
TestMu AI forEnterprise
Get access to solutions built on Enterprise
grade security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests