

Power Your Software Testing with AI Agents and Cloud
The Native AI-Agentic Cloud Platform to Supercharge Quality Engineering. Test Intelligently and Ship Faster.


- TestMu AI (Formerly LambdaTest)
- /
- Learning Hub
- /
- What Is Performance Engineering: A Comprehensive Guide
What Is Performance Engineering: A Comprehensive Guide
Performance engineering builds speed and scalability into software from the design stage. Learn its phases, tools, SLO metrics, and the engineer role.
Last Updated on:
On This Page
- What is Performance Engineering?
- Importance of Performance Engineering
- Performance Engineering vs Performance Testing
- Performance Engineering vs APM
- Integrating with Service Management
- SLAs, SLOs, and SLIs
- Key Concepts of Performance Engineering
- Phases of Performance Engineering
- Tools for Performance Engineering
- Advantages of Performance Engineering
- Disadvantages of Performance Engineering
- Best Practices for Performance Engineering
- Performance Engineer: Role & Responsibilities
- Performance Engineering for LLM Applications
- How TestMu AI Elevates Performance Engineering
- Future of Performance Engineering
- Conclusion
Performance engineering is the practice of building speed, scalability, and stability into software from the design stage instead of fixing them after release. Teams set Service Level Objectives on percentiles such as P95 and P99, then use profiling, load testing, and capacity planning to hold the system inside those targets. This guide covers what performance engineering is, why it matters, how it differs from performance testing and APM, SLAs, SLOs, and SLIs, key concepts, phases, tools, advantages, disadvantages, best practices, the performance engineer role, and how the practice changes for AI and LLM applications.
Key Takeaways
- Performance engineering treats speed, scalability, and stability as design requirements from the requirements stage, rather than as defects to fix after release.
- Performance testing validates a finished build under simulated load, while performance engineering also covers architecture review, profiling, capacity planning, and production monitoring.
- Application Performance Management detects problems already affecting live users, so a team that treats an APM tool as its performance strategy keeps reacting to problems built into the design months earlier.
- A Service Level Objective must be set stricter than the Service Level Agreement it backs, and the gap between the two is the error budget a team can spend before customers are owed service credits.
- Performance objectives belong on percentiles such as P95 and P99, because an average response time hides the long-tail latency that drives churn, timeouts, and cascading failures.
- Large language model applications are measured by time to first token and inter-token latency instead of a single response time, because the answer streams token by token.
What is Performance Engineering?
Performance engineering is the practice of designing, testing, and optimizing software to meet defined speed, scalability, and responsiveness goals. It analyzes system behavior under load, identifies bottlenecks through testing and profiling, and improves code, databases, and configurations to ensure reliable, efficient operation at scale.
Key Takeaway: Performance engineering analyzes system behavior under load, finds bottlenecks through testing and profiling, and tunes code, databases, and configuration so software runs reliably at scale.
Importance of Performance Engineering
Performance engineering is needed for software delivery that always does meet the hopes of expectations of both users and businesses. The following points highlight its key importance:
- Delivers a Better User Experience: Performance engineering helps ensure applications run smoothly in response quickly. Systems for fast loading improve customer satisfaction. Since the systems load quickly, user delays are reduced.
- Detects Issues Early in Development: Teams address performance during the early stages of the software lifecycle, and they can identify and fix potential bottlenecks before they reach production. This can reduce much costly rework along with the risk of more last-minute fixes.
- Improves System Efficiency: Applications which are well-optimized make for better use of computing resources like memory, CPU, and network bandwidth. Infrastructure costs are lowered and systems become more stable.
- Supports Scalability and Growth: Systems are ensured through performance engineering to handle increasing traffic or workload without slowing down. This is especially important. Applications can be expected to grow over time.
- Minimizes Downtime and Failures: Managing performance proactively is a useful preventative measure. Specifically, it may avert crashes, timeouts, and system failures. This improves reliability and protects business continuity.
- Speeds Up Release Cycles: By integrating performance checks into continuous integration and deployment workflows, development teams can release updates faster while maintaining quality.
- Strengthens Business Value: Reliable and high-performing software contributes directly to customer retention, positive brand perception, and increased revenue.
Key Takeaway: Performance engineering matters because catching bottlenecks early lowers rework cost, cuts infrastructure spend through efficient resource use, and keeps applications stable as traffic grows.
Performance Engineering vs Performance Testing
Performance engineering with performance testing are closely related, though they exist for different purposes within the software development lifecycle. Performance engineering has the aim of designing and building systems for optimal performance from the beginning. It is a continuous proactive process. Performance testing reacts to systems and it focuses on validating system performance under specific conditions, usually after development is complete.
| Aspect | Performance Engineering | Performance Testing | Application Performance Management (APM) |
|---|---|---|---|
| Approach | Proactive; integrated throughout the development lifecycle | Reactive; conducted after development is complete | Reactive; runs continuously against live production |
| Goal | Prevent performance issues through design and optimization | Identify performance issues under simulated conditions | Detect and diagnose issues already affecting real users |
| Scope | Involves design, architecture, coding, monitoring, and tuning | Focuses on executing tests like load, stress, and endurance tests | Monitors live traces, metrics, and transactions in production |
| Timing | Begins early in the software development lifecycle | Performed near the end or after development | Always on, after deployment |
| Techniques | Includes profiling, capacity planning, architectural analysis | Involves simulating traffic and analyzing system response | Distributed tracing, real user monitoring, alerting |
| Tools | Uses APM tools, profilers, architecture review methods | Uses tools like JMeter, LoadRunner, and Gatling | Uses New Relic, Datadog, Dynatrace, or Splunk AppDynamics |
| Outcome | Builds systems that are scalable, reliable, and efficient | Validates if the system meets performance requirements | Fast detection and diagnosis of live incidents |
| Integration with DevOps | Closely aligned with CI/CD and shift-left strategies | Often treated as a separate phase before release | Feeds production signals back to development and operations |
Key Takeaway: Performance testing uses load generators such as JMeter, LoadRunner, and Gatling to validate a system near the end of development, while performance engineering uses profiling, capacity planning, and architectural analysis from the design stage onward.
Performance Engineering vs Application Performance Management (APM)
The table above adds APM as a third column, and the distinction deserves unpacking, because the two are routinely confused and teams often buy one believing they have bought the other.
Application Performance Management (APM) is a reactive discipline. It watches software that is already running in production, collecting traces, metrics, and transaction data so that when performance degrades you find out quickly and can diagnose where. Tools such as New Relic, Datadog, Dynatrace, and Splunk AppDynamics live in this space. AppDynamics was merged into Splunk in 2025 and its documentation now ships under the Splunk AppDynamics name, so a vendor list that still treats Cisco AppDynamics as a separate product is out of date. APM answers the question: what is happening right now, and where does it hurt?
Performance engineering is proactive and end-to-end. It designs performance into the system from requirements onwards, through architecture, code, testing, and tuning, so that the problems APM would have caught never reach production. It answers a different question: how do we build something that will not degrade under the load we expect?
The relationship is not competitive. APM is one of the instruments performance engineering uses, and it is where the discipline gets its feedback loop. A performance engineer reads APM data from production to learn what real users actually experience, then feeds that back into design decisions and test scenarios, so the next release is built on evidence rather than assumption.
The practical failure is buying APM and calling it a performance strategy. Monitoring tells you the checkout is slow at peak. It does not tell you the architecture cannot scale, and it will not redesign the query that caused it. APM detects, performance engineering prevents, and a team with only the first is permanently reacting to problems it designed in months earlier.
Key Takeaway: A performance engineer reads Application Performance Management data from production to learn what real users experience, then feeds the findings back into design decisions and test scenarios for the next release.
Integrating Performance Engineering with Service Management
Performance engineering is often treated as a purely technical concern, which is how it ends up disconnected from the people accountable for the service. In organisations that run IT Service Management (ITSM) under a framework such as ITIL, performance engineering has a natural home inside three established practices, and plugging into them is what turns performance from an engineering preference into an operational commitment.
Capacity Management
Capacity Management is concerned with ensuring the infrastructure can meet demand, now and in future, at a justifiable cost. This is where performance engineering contributes its most valuable output: evidence. Load testing and profiling produce the numbers that turn capacity planning from an argument into a calculation, such as how many concurrent users a node actually supports before latency degrades, and where the ceiling sits.
Without that input, capacity decisions default to guesswork in one of two directions: over-provisioning, which is expensive but invisible, or under-provisioning, which is cheap until the day it is catastrophic. Performance engineering also supplies the forward view, modelling what next year's growth or a seasonal peak will require while there is still time to act.
Service Level Management
Service Level Management owns the performance commitments made to the business and to customers, and it is where performance targets stop being aspirations. Performance engineering makes those targets real in both directions: it validates before release that the system can actually meet the agreed levels, and it defines what is realistically achievable in the first place, so the organisation does not sign up to a latency target its architecture cannot support.
This is the practice that the SLA, SLO, and SLI hierarchy below belongs to.
Problem Management
Problem Management is distinct from incident management, and the difference matters. Incident management restores service, so the site is slow, you scale out, the alert clears. Problem management asks why it happened and removes the cause so it cannot recur.
Performance engineering is what makes that possible for performance problems, because the root cause is usually architectural rather than operational. Restarting the service fixed the incident; the unbounded query that exhausted the connection pool is still there. Performance engineers bring the profiling, tracing, and load reproduction needed to find the real cause, and the design authority to change it, which is what stops the same incident returning every quarter.
The value of this integration is organisational rather than technical. When performance engineering feeds capacity, service level, and problem management, performance becomes something the business has agreed to and can hold someone to, rather than a quality engineers advocate for and trade away when the deadline tightens.
Key Takeaway: Connecting performance engineering to ITIL capacity management, service level management, and problem management turns performance from an engineering preference into an operational commitment the business has agreed to.
Defining Performance Metrics: SLAs, SLOs, and SLIs
"The application should be fast" is not a performance target, because nobody can tell you whether it was met. The SLI, SLO, and SLA hierarchy exists to turn that sentiment into something measurable, agreed, and enforceable. The three are used interchangeably in conversation and they are not interchangeable at all: each is built on the one before it.
| Term | What it is | Example | Consequence if missed |
|---|---|---|---|
| SLI (Service Level Indicator) | The raw measurement itself | P95 checkout latency = 380ms | None, it is just a number |
| SLO (Service Level Objective) | Your internal target for that SLI | P95 checkout latency under 500ms, 99.9% of the time | Internal: engineering effort shifts to reliability |
| SLA (Service Level Agreement) | The contractual promise to the customer | 99.5% availability per month | External: financial penalties or service credits |
Read bottom-up, it is straightforward. The SLI is what you measure. The SLO is the line you draw on it. The SLA is what you promised someone else, with money attached.
The rule that follows is the one teams get wrong: your SLO must be stricter than your SLA. If you promise customers 99.5% and target 99.5% internally, you breach the contract the first time you miss. Setting the SLO at 99.9% against a 99.5% SLA gives you a buffer, and that gap is your error budget, the amount of unreliability you can spend before anyone is entitled to a refund.
Three choices decide whether these work in practice:
- Measure percentiles, not averages: An SLO on mean latency is close to worthless, because the mean hides exactly the long-tail latency that drives users away. Set objectives at P95 or P99 so the target speaks for the users having the worst experience rather than the typical one.
- Pick SLIs users can feel: Latency, error rate, throughput, and availability qualify. CPU utilisation does not, since no customer has ever cared about it directly. If an SLI can go red while every user is perfectly happy, it is a diagnostic signal, not a service level.
- Set targets you can meet, not targets that sound good: This is where performance engineering earns its place in Service Level Management. Load testing tells you what the architecture can actually sustain, so the SLO is grounded in evidence rather than optimism, and the SLA is not a promise the system was never able to keep.
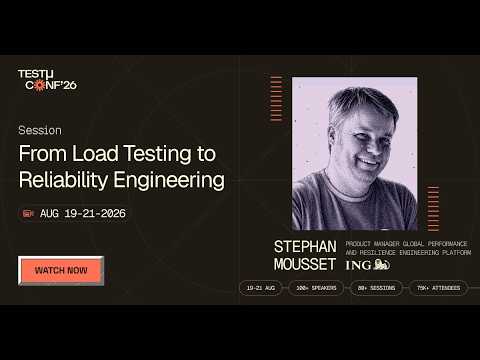
In this TestMu Conf 2026 session, From Load Testing to Reliability Engineering: Making Performance Testing Predict Production Behavior, Stephan Mousset covers why load tests that produce large volumes of data and detailed reports still leave teams unable to answer whether a change is safe in production, and how to make performance testing predict production behavior instead.
Key Takeaway: A Service Level Indicator is the raw measurement, a Service Level Objective is the internal target set on that measurement, and a Service Level Agreement is the contractual promise carrying financial penalties.
Key Concepts of Performance Engineering
Performance engineering is built around a set of core concepts that are guiding software systems designed, built, and maintained for high performance. To meet technical as well as business goals, these concepts help teams to plan proactively and to continuously optimize their systems.
- Lifecycle-Wide Optimization: Performance engineers optimize performance as they focus throughout every stage of the software lifecycle. By embedding testing early in development, teams can monitor and improve performance continuously from coding through production.
- Collaborative Responsibility: It emphasizes teamwork across development, quality assurance, and business teams. Maintaining application performance becomes a shared responsibility, which leads to quicker releases and better user satisfaction.
- Performance Governance with Centers of Excellence: A Testing Center of Excellence (CoE) plays a vital role in unifying testing standards. It drives at the best practices then consolidates the data from the teams. Thus a consistent approach for performance validation is surely ensured.
- Dedicated Performance Engineering Role: Performance engineers think of performance when development is in the early stages. They work together with developers to help make systems perform well. Ahead of production, the system meets performance benchmarks.
- Active Developer Participation: Developers are actively participating in performance validation. Teams can detect as well as resolve inefficiencies before the software is released through shifting performance-related checks leftward.
- DevTesters as Performance Accelerators: DevTesters operate at the intersection of development and performance. During development, they actively test for performance in an agile lightweight way so that applications may meet standards required early.
- Post-Deployment Monitoring by Business Stakeholders: Business analysts and application engineers monitor applications in live environments. Alignment with user expectations and with business goals is indeed ensured by the doing of this. After deployment, they give feedback which sustains performance and loops.
Key Takeaway: Performance engineering works as a shared responsibility across developers, QA, and business teams, supported by a Testing Center of Excellence and a dedicated performance engineer role.
Phases of Performance Engineering
Performance engineering follows a structured lifecycle designed to ensure software's speed, stability, with scalability from development through production. Each phase helps us identify, address and monitor performance during the system evolution.
1. Requirements Gathering and Architecture Understanding
This initial phase involves understanding the system architecture along with defining non-functional and functional requirements. Performance goals are documented. The documentation includes user load expectations, response time targets and scalability metrics.
2. Performance Modeling and Simulation
Teams create predictive models to estimate how the application will behave under various conditions. These simulations help evaluate performance under stress scenarios such as peak traffic, degraded network conditions, or heavy concurrent usage.
3. Performance Profiling and Code Analysis
This phase focuses on identifying performance bottlenecks at the code and component levels. Checking application logic, database queries, memory usage, also third-party dependencies entails detecting issues such as inefficient processing or memory leaks.
4. Performance Testing
Engineers simulate realistic load conditions to validate system performance under pressure. Tests may include load testing, stress testing, and endurance testing to ensure the application remains responsive and stable during high usage.
The environment those tests run in decides whether the numbers mean anything. AWS Prescriptive Guidance builds its performance engineering approach on four pillars for the test environment: test-data generation, test observability, test automation, and test reporting. Test data is the pillar teams skip most often. A query that runs fast against a small synthetic table can pick a different execution plan against a production-sized one, so the test passes and the release still fails. Match the data volume, the cache state, and the downstream dependencies to production before you treat a result as evidence.
5. Analysis and Optimization
Once testing is complete, the results are analyzed to identify root causes of latency or instability. Engineers then fine-tune the application by refactoring code, optimizing configurations, or scaling infrastructure components.
6. Deployment and Real-World Monitoring
After deployment, continuous monitoring tools are used to track key performance indicators (KPIs) in the production environment. Metrics like response time, throughput, error rates, and resource utilization help detect anomalies and support ongoing improvements.
7. Feedback and Continuous Improvement
Feedback loops from monitoring data and user behavior inform iterative performance enhancements. This ensures that performance engineering remains an ongoing practice as the application evolves and scales.
Key Takeaway: The performance engineering lifecycle runs through seven phases: requirements gathering, performance modeling and simulation, profiling and code analysis, performance testing, analysis and optimization, deployment monitoring, and continuous feedback.
Tools for Performance Engineering
Performance engineering relies on a diverse set of tools that support testing, monitoring, profiling, and optimization across the entire software lifecycle. Selecting the right tools depends on the application architecture, performance goals, and the level of automation and observability required.
Load and Performance Testing Tools
- Tools: Apache JMeter, Gatling, k6, Locust
- Performance Testing Tools are used to simulate user traffic and test system behavior under various load conditions. Helps identify bottlenecks and validate scalability.
Application Performance Monitoring (APM)
- Tools: Dynatrace, New Relic, Splunk AppDynamics
- Provides real-time visibility into application performance. Tracks metrics such as response times, error rates, and transaction traces.
Infrastructure Monitoring
- Tools: Prometheus, Grafana, Datadog
- Monitors the health and resource usage of servers, containers, and network components. Essential for understanding backend system performance.
Code Profiling and Analysis Tools
- Tools: VisualVM, YourKit, dotTrace, Py-Spy
- Helps developers find inefficient code, memory leaks, and high-latency operations. Supports deep analysis and optimization at the code level.
Frontend and Browser Performance Tools
- Tools: Google Lighthouse, WebPageTest, Chrome DevTools
- Evaluates page load speed, rendering time, and overall frontend performance. Important for optimizing user experience in web applications.
Frontend performance has published thresholds to test against, so a team no longer has to argue about what counts as fast enough. Google's Core Web Vitals define three targets, each judged at the 75th percentile of real page loads: Largest Contentful Paint at or under 2.5 seconds, Interaction to Next Paint at or under 200 milliseconds, and Cumulative Layout Shift at or under 0.1. Interaction to Next Paint replaced First Input Delay as a Core Web Vital in March 2024, so a dashboard or test plan that still reports First Input Delay is tracking a retired metric. Lighthouse measures a single synthetic run in a lab, while the Chrome User Experience Report supplies the field data those thresholds are scored against, and the two often disagree. Use the lab run to debug a regression and the field data to decide whether you have one.
CI/CD Integration Tools for Performance Testing
- Tools: Jenkins, GitLab CI, Azure DevOps, Bamboo
- Enables automation of performance testing within the deployment pipeline. Ensures that performance checks are part of continuous delivery workflows. To scale these runs across a cloud grid and finish large suites faster with parallel execution, review the HyperExecute pricing plan to match a tier to your workload.
Observability and Log Analysis Tools
- Tools: ELK Stack, Splunk
- Used to collect, search, and analyze logs for diagnosing performance issues. Enhances visibility in distributed and production environments.
One decision sits above this tool list: how you instrument the application in the first place. OpenTelemetry is now the vendor-neutral standard for emitting traces, metrics, and logs, and it is a Cloud Native Computing Foundation project rather than any single vendor's format. You instrument once against the OpenTelemetry API and export over OTLP to whichever backend you run, and Datadog, New Relic, Dynatrace, Grafana, and the open-source collectors all accept it. The gain is that switching observability vendors stops being a re-instrumentation project. The cost is that you now own the collector configuration and the sampling decisions a proprietary agent used to make for you.
Key Takeaway: Performance engineering tooling spans load generators such as JMeter and k6, APM platforms, infrastructure monitors, code profilers, and frontend tools, and OpenTelemetry lets a team instrument an application once and export to any of those backends.
Advantages of Performance Engineering
Performance engineering delivers measurable value across the software development lifecycle by ensuring systems are designed, built, and maintained to perform reliably under real-world conditions. Its benefits extend beyond technical performance to include operational efficiency and strategic business impact.
- Enhanced User Experience: Applications that are responsive and consistently available provide a smoother, more satisfying experience, improving user retention and engagement.
- Proactive Issue Identification: Performance issues are detected and addressed during early development phases, reducing the risk of critical failures in production and lowering the cost of remediation.
- Increased System Stability and Reliability: By validating performance under various load scenarios, systems are better prepared to handle peak demand without degradation or outages.
- Improved Scalability: Applications are architected with growth in mind, ensuring they can scale efficiently to accommodate increasing user loads or data volumes.
- Efficient Resource Utilization: Optimized performance reduces excessive consumption of CPU, memory, storage, and bandwidth, resulting in more cost-effective infrastructure management.
- Accelerated Time to Market: Integrating performance validation into automated development and deployment pipelines enables faster and more confident releases.
- Reduced Risk of Post-Deployment Failures: By addressing potential bottlenecks and latency issues pre-release, performance engineering minimizes the likelihood of production incidents.
- Business Continuity and Competitive Advantage: High-performing systems support business-critical operations, enhance customer trust, and contribute to long-term growth and profitability.
Key Takeaway: The main advantages of performance engineering are better user retention, cheaper early defect fixes, higher system stability under peak demand, efficient resource use, and faster releases.
Disadvantages of Performance Engineering
While performance engineering adds significant value to software development, it also comes with certain limitations and challenges. Understanding these drawbacks helps organizations plan and allocate resources more effectively.
- Increased Initial Investment: Implementing performance engineering requires upfront costs in tools, infrastructure, and skilled personnel. This can be a barrier for small teams or early-stage projects.
- Complex Tooling and Integration: Integrating performance tools into the development and CI/CD pipeline can be technically complex. Ensuring compatibility across systems may require additional effort.
- Steep Learning Curve: Performance engineering involves specialized knowledge in areas like system architecture, profiling, and load modeling. Teams may need training to effectively adopt best practices.
- Extended Development Time: Adding performance validation and optimization to each phase of development can slow down release cycles if not well-managed, especially in fast-paced agile environments.
- Difficult Bottleneck Isolation: In large, distributed, or microservices-based systems, identifying the exact source of a performance issue can be time-consuming and require advanced debugging skills.
- Resource Overhead During Testing: Simulating high-load environments or executing performance tests at scale may require significant compute resources, impacting cost and test environment stability.
- Potential Over-Optimization: Over-focusing on performance can lead to premature optimization, where time is spent improving areas that do not impact user experience or business outcomes meaningfully.
- Long-Tail Latency Problems: Averages hide the users who suffer. A system with a 200ms mean response time can still be failing the slowest 1% of requests at several seconds, and that long-tail latency is disproportionately where churn, timeouts, and cascading failures originate. Chasing it is genuinely hard: tail latency is caused by rare, compounding conditions such as garbage collection pauses, cache misses, lock contention, and noisy neighbours, which are difficult to reproduce under test and often only surface at production scale. Measuring at P95 and P99 rather than the mean is the minimum defence.
- Time-Consuming Root-Cause Analysis: Detecting that performance degraded is quick. Establishing why is not. In a distributed system a single slow transaction may cross a dozen services, and the root cause may be several hops from where the symptom appears, so a database index, a downstream retry storm, and an undersized connection pool can all present identically as a slow endpoint. Root-cause analysis of this kind consumes senior engineering time, and it is the reason distributed tracing and correlated observability data are worth the investment before you need them.
Key Takeaway: Performance engineering costs upfront investment in tools and skilled staff, complicates CI/CD integration, and makes root-cause analysis slow in distributed systems where one slow endpoint can have many unrelated causes.
Best Practices for Performance Engineering
To ensure consistent, scalable, and reliable software performance, organizations must adopt disciplined and repeatable practices across the development lifecycle. Below are key best practices widely recognized in the industry:
- Define Clear Performance Objectives: Establish measurable performance goals early in the project, such as acceptable response times, throughput, and resource usage. These targets should align with business requirements and user expectations.
- Shift Performance Left: Integrate performance considerations during the earliest stages of software development, including architecture design, coding, and build processes. This reduces the cost and complexity of fixing issues later.
- Model Realistic Workloads: Simulate real-world usage patterns based on actual user behavior, including peak load scenarios and edge cases. Accurate modeling ensures that tests reflect real application conditions.
- Incorporate Continuous Performance Testing: Embed automated performance tests within the CI/CD pipeline to validate performance during every build. This supports faster feedback loops and earlier issue detection.
- Use End-to-End Monitoring and Observability: Deploy performance monitoring tools in staging and production environments to capture metrics like latency, error rates, and system health. Observability enables real-time detection and proactive resolution.
- Profile and Tune Regularly: Perform regular profiling of code, queries, and infrastructure components to identify inefficiencies. Continuous tuning ensures that performance does not degrade as features are added or usage scales.
- Collaborate Across Teams: Foster cross-functional collaboration between developers, testers, performance engineers, and business stakeholders. Shared responsibility improves test coverage and speeds up decision-making.
- Avoid Premature Optimization: Focus on optimizing areas that directly impact performance objectives. Avoid investing time in parts of the system that have negligible user or business impact.
- Maintain a Performance Baseline: Establish and regularly update performance baselines to track improvements or regressions over time. Baselines provide reference points for tuning and release readiness.
- Learn from Production Feedback: Use insights from production monitoring, incident reports, and user feedback to improve test strategies and address performance gaps in future iterations.
Key Takeaway: Best practice in performance engineering is to set measurable targets early, shift testing left into CI/CD, model realistic workloads, maintain performance baselines, and avoid optimizing areas with no user impact.
Performance Engineer: Role & Responsibilities
A Performance Engineer plays a critical role in ensuring that software systems are fast, reliable, scalable, and efficient across all stages of development and deployment. Their responsibilities span from designing performance strategies to monitoring production environments, making them integral to both development and operations teams.
Key Responsibilities of a Performance Engineer
- Define Performance Requirements: Collaborate with stakeholders to gather and document non-functional requirements such as response time, throughput, concurrency, and resource utilization targets.
- Design for Performance: Participate in architectural and design reviews to ensure the system is built with scalability and efficiency in mind. Suggest frameworks, patterns, or configurations that support optimal performance.
- Develop Performance Test Strategies: Create and maintain test plans that simulate realistic load conditions, including load testing, stress testing, soak testing, and spike testing.
- Execute and Automate Performance Tests: Use tools like JMeter, k6, Gatling, or LoadRunner to simulate user behavior. Automate test scripts and integrate them into CI/CD pipelines to support continuous performance validation. TestMu AI's cloud performance testing runs existing JMeter and Gatling scripts on managed load generators, so that pipeline step does not depend on a self-hosted load fleet.
- Analyze Results and Identify Bottlenecks: Interpret performance test results, monitor key performance indicators (KPIs), and trace root causes of latency, failures, or resource constraints.
- Collaborate with Development and DevOps Teams: Work closely with developers to optimize code and with DevOps teams to tune infrastructure and deployment configurations for maximum performance.
- Support Monitoring and Observability: Implement and configure monitoring tools (e.g., Dynatrace, New Relic, Prometheus, Grafana) to track performance in real time, especially in production environments.
- Recommend Improvements and Best Practices: Provide actionable insights and optimization recommendations based on profiling and test data. Advocate for performance-conscious coding, configuration, and deployment practices.
- Stay Updated with Trends and Tools: Continuously research emerging performance engineering tools, methodologies, and industry standards to enhance team capabilities and project outcomes.
How to Become a Performance Engineer
Almost nobody starts here. Performance engineering is a discipline people arrive at, usually from QA, development, or operations, because it asks you to understand the whole system rather than one layer of it. That breadth is why it is rarely an entry-level role.
On the degree question: a bachelor's in computer science, software engineering, or a related field is the conventional route, and it is what most job listings ask for. It is not a hard requirement. Employers hiring performance engineers care considerably more about demonstrable ability, since this is a role where you can show your work: a load test you designed, a bottleneck you found, a latency figure you moved. Plenty of strong performance engineers come from QA or sysadmin backgrounds without a CS degree. What a degree genuinely helps with is the theory underneath the tooling, such as algorithmic complexity, concurrency, operating systems, and networking, and that theory is what separates someone who can run JMeter from someone who can explain why the P99 is bad.
What actually makes a good one:
- Be able to code, not just script: You need to read the application you are testing. Finding a bottleneck is one thing; being credible when you tell a developer their query is the problem is another.
- Learn the stack beneath the app: Most real bottlenecks live in the database, the network, the JVM, or the connection pool rather than in application logic. Performance problems do not respect the boundaries of your job description.
- Get fluent with the tooling: A load generator such as JMeter, k6, or Gatling, plus an APM and a profiler. The tools are the easy part and the part courses teach, which is why they are the least differentiating.
- Think in percentiles and statistics: Knowing why the mean misleads, what a P99 actually represents, and how to tell a real regression from noise. This is the skill most commonly missing.
- Develop an investigative instinct: The job is diagnosis. Forming a hypothesis, isolating a variable, and resisting the obvious answer matters more than any certification, because the first plausible cause is frequently the wrong one.
- Communicate to non-engineers: You will spend real time convincing people to spend money or delay a release on evidence they cannot see. Translating "P99 latency degrades beyond 5,000 concurrent users" into what it costs the business is what makes the rest of the work count.
A workable path: start in QA or development, take ownership of the performance tests nobody else wants, learn to read profiles and APM traces, and build the habit of asking why rather than reporting that. The title tends to follow the work.
Key Takeaway: A performance engineer defines performance requirements, reviews architecture for scalability, automates load tests, and diagnoses bottlenecks, and the role is usually reached from QA, development, or operations rather than entered directly.
How Does Performance Engineering Change for AI and LLM Applications?
It changes what you measure. A large language model streams its answer token by token, so a single response time figure no longer describes what the user experiences. The two measurements that replace it are time to first token (TTFT), the interval from submitting the query to receiving the first token, and inter-token latency (ITL), the average gap between consecutive tokens, which is also called time per output token (TPOT). NVIDIA's benchmarking guide defines ITL as end-to-end latency minus TTFT, divided by the number of output tokens minus one, so TTFT is deliberately excluded from it. Throughput is counted in output tokens per second alongside the requests per second you already track. The NVIDIA NIM benchmarking metrics reference gives the full definitions.
Instrumentation has caught up with this. OpenTelemetry's generative AI conventions now live in a dedicated repository, and the GenAI metrics specification defines gen_ai.server.time_to_first_token, gen_ai.server.time_per_output_token, and gen_ai.client.token.usage, alongside agent-level metrics such as gen_ai.invoke_agent.tool_calls and gen_ai.execute_tool.duration. Every metric in that document currently carries Development stability, so treat the names as provisional and pin the convention version your dashboards are built against.
Load generation needs its own tooling. AIPerf, the successor to GenAI-Perf, drives OpenAI-compatible chat completion, embedding, and multimodal endpoints, and reports time to first token, inter-token latency, request latency, and output token throughput at P50, P90, and P99. The discipline itself does not change. You still set objectives on percentiles, still model a realistic workload, and still trace a slow response back to its cause. What changes is the shape of the workload, because an agent that calls tools in a loop turns one user action into an unpredictable number of model calls, which widens the tail and makes the cost of a request a count of tokens as well as milliseconds.
Key Takeaway: Performance engineering practice does not change for LLM applications, but an agent that calls tools in a loop turns one user action into an unpredictable number of model calls, which widens the latency tail.
How TestMu AI Elevates Performance Engineering
TestMu AI allows performance engineers to execute automated and manual tests on a real browser cloud, ensuring applications perform consistently across diverse environments. This capability is crucial for detecting and resolving issues that directly affect end-user experience.
Why HyperExecute Matters for Performance Testing
Unlike conventional cloud grids or simulators, HyperExecute is optimized for low-latency, intelligent test distribution. It not only accelerates execution but also ensures performance bottlenecks are identified quickly, shortening feedback loops and improving developer productivity.
- AI-Native Test Orchestration: Tests are grouped and distributed intelligently across environments. Past test run data is used to reorder tests, surface failures faster, and optimize execution.
- Up to 70% Faster Test Execution: over traditional cloud-based Selenium grids or legacy setups.
- Multi-OS and Multi-Framework Support: Works on Linux containers, macOS, Windows; supports multiple languages and frameworks (e.g., Selenium, Cypress, Playwright, Appium).
- Real-Time Logs, Dashboards, and Reports: Single dashboard view with test execution logs (terminal, network, commands, failures), automatic report generation, visual insights.
- Parallel & Scalable Testing: Run tests in parallel across many browser-device combinations; gutter in concurrency control.
- Test Split: Different modes to split test suites as needed (smart auto-split, matrix, hybrid) to get faster results.
- Artifact & Dependency Management: Automatically handles test artifacts (logs, videos, etc.), caching dependencies for faster future runs.
- Security, Compliance & Private Cloud Options: Data encryption, private/cloud-runner options, compliance with standards like GDPR, SOC2 etc.
- HyperExecute MCP Server & AI-Enhanced Configuration: Rapid setup of test configurations via Model Context Protocol, auto-generation of YAML, less manual boilerplate.
Future of Performance Engineering
The next evolution of performance engineering will be shaped by AI, machine learning, and cloud-native architectures. AI-driven anomaly detection, predictive performance modeling, and autonomous scaling will allow systems to self-optimize. As organizations increasingly adopt microservices, serverless computing, and edge platforms, performance engineering will continue to expand as a critical business enabler.
Key Takeaway: The future of performance engineering points to AI-driven anomaly detection, predictive performance modeling, and autonomous scaling, as microservices, serverless, and edge platforms spread.
Conclusion
Performance engineering is no longer optional in today's high-demand digital environment. It is a strategic discipline essential for building reliable, scalable, and user-centric software systems. By integrating performance practices early and continuously, teams can proactively detect issues, reduce operational costs, and deliver seamless user experiences.
Whether you're building a real-time trading platform, a global SaaS application, or a responsive web interface, performance engineering ensures your system is built not just to function but to excel under pressure.
Author
Anupam Pal Singh
Blogs: 11


Anupam is a Community Contributor at TestMu AI with 4+ years of experience in software testing, AI, and web development. At TestMu AI, he creates technical content across blogs, tool pages, and video scripts, with a focus on CI/CD, test automation, and AI-powered testing. He has authored 25+ in-depth technical articles on the TestMu AI Learning Hub and holds certifications in Automation Testing, Selenium, Appium, Playwright, Cypress, and KaneAI.


Performance Engineering FAQs
Did you find this page helpful?
More Related Learning Hubs
TestMu AI forEnterprise
Get access to solutions built on Enterprise
grade security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests