
Power Your Software Testing with AI Agents and Cloud
The Native AI-Agentic Cloud Platform to Supercharge Quality Engineering. Test Intelligently and Ship Faster.


- TestMu AI (Formerly LambdaTest)
- /
- Blog
- /
- How to Test a Chatbot Without Code
How to Test a Chatbot Without Code (2026 Guide)
How to test a chatbot without code: autonomous AI evaluators chat like real users and score every reply on 9 quality metrics. No scripts to write or maintain.
Last Updated on:
TestMu AI tests a chatbot without code by taking a context document, a plain-English description of correct behavior, and a list of hard rules, then sending autonomous evaluators to chat with it and grade the results. Because a chatbot rewords every answer, this catches an invented policy or a broken hand-off rule that a fixed-string Botium assertion would miss.
What does testing a chatbot without code actually mean?
It means you never write an assertion or a test script. You describe the bot's job in plain English, and an AI evaluator does both the conversing and the judging. The thing being checked changes from a fixed value to a described behavior.
A Selenium test can assert that a button reads "Submit" because that value is fixed. A chatbot has no fixed value to check. The same question returns a different answer every run, so there is no selector and no string to compare against. TestMu AI works around that by asking you for three things instead of a script:
- A context document, which can be the knowledge base the bot answers from, a PRD, or a written description of what it does
- A plain-English prompt that defines correct behavior, for example a support bot for Acme that handles billing, account, and product questions and stays concise and accurate
- The hard rules it must never break, such as never invent a policy or a price, and always offer to hand off to a human
From those three inputs the platform figures out what to test and how to grade it. Nobody writes a convo file, and nobody maintains a brittle assertion when the bot's wording shifts. For the wider method beyond this no-code route, from test cases to metrics and automation, see how to test a chatbot.
Why can't a scripted test verify a chatbot's answers?
Because a scripted test asserts on an exact substring, and a chatbot rephrases a correct answer on every run. Here is a single ask-about-support-hours exchange in a typical Botium setup:
const { BotDriver } = require('botium-core')
const { assert } = require('chai')

const driver = new BotDriver()
const container = await driver.Build()
await container.Start()

await container.UserSaysText('What are your support hours?')
const reply = await container.WaitBotSays()
assert.include(reply.messageText, '9 AM to 5 PM')

await container.Stop()
await container.Clean()
Even this short a script is fragile, and the fragility is specific to chatbots. The assertion looks for one exact phrase. The moment the bot answers "Our hours are 9 to 5" instead of "9 AM to 5 PM," a correct reply fails the test. It also only ever covers the one phrasing of the one intent you scripted, so every new way a user might ask becomes another convo file, and a real bot carries hundreds of intents.
That maintenance is the dominant cost of a scripted bot suite. Every prompt tweak or model update means rewriting string assertions rather than adding coverage. And someone still has to write JavaScript to begin with. A manual QA engineer, a PM, or a founder with no automation engineer ends up testing the bot by hand, slowly, and never against the angry or off-script users who break it in production.
How do you test a chatbot without writing scripts?
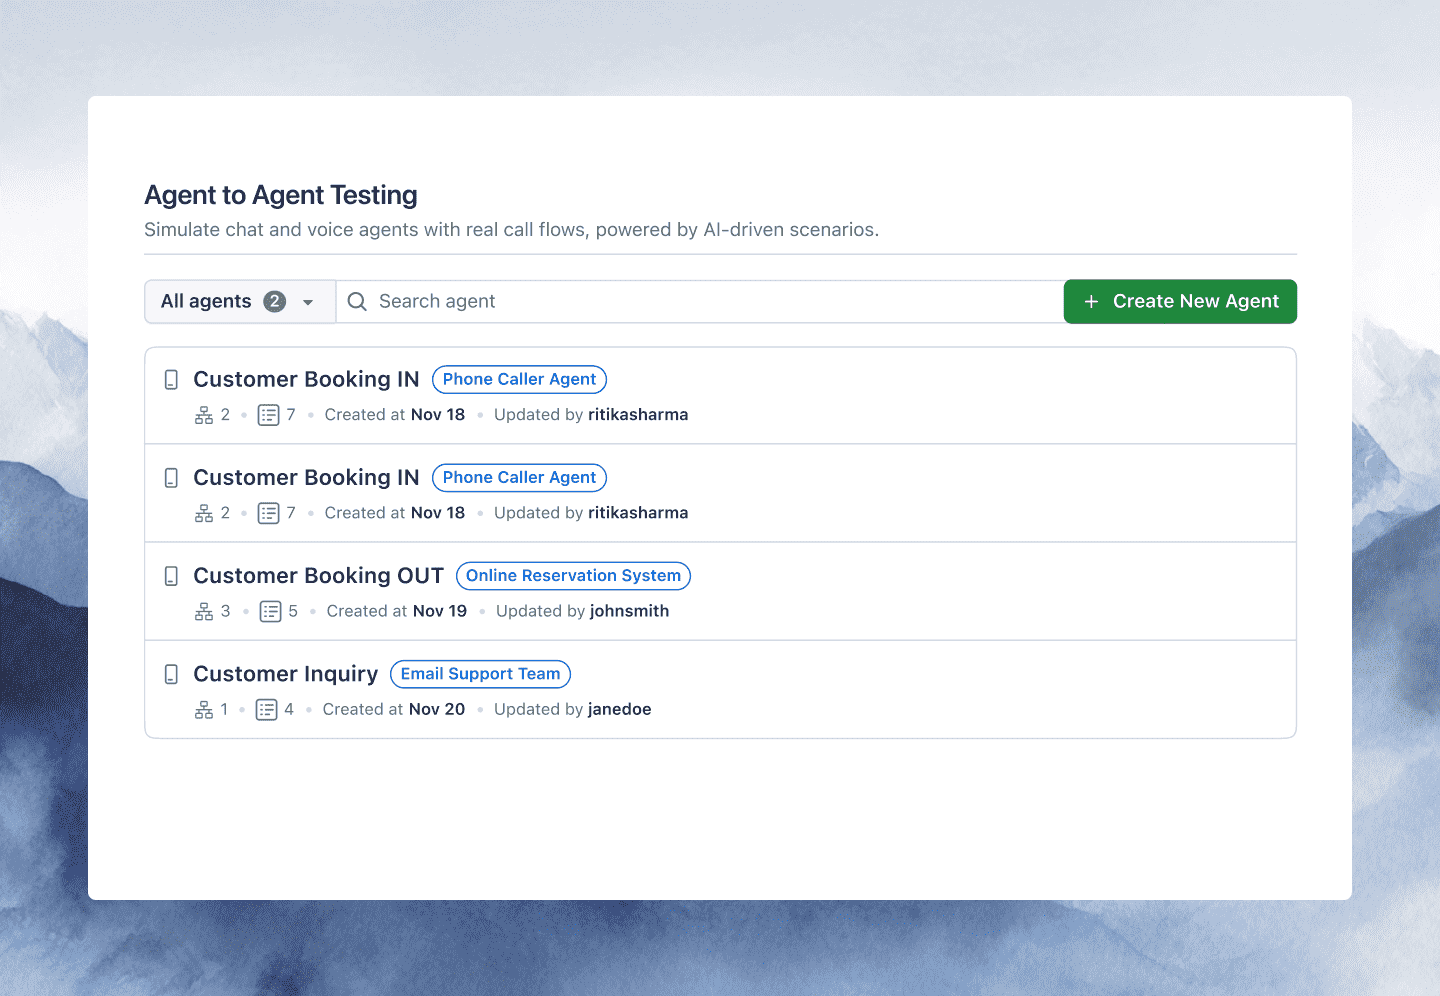
You point TestMu AI at your bot, describe it once, and let its autonomous evaluators run the conversations. With TestMu AI chatbot testing, the setup for a standard chat agent takes under 30 minutes and looks like this:
- Connect the chatbot endpoint, or point the platform at the chat widget
- Describe what the bot is for in one plain-English prompt
- Add the rules it must never break and the personas you care about, such as a confused first-timer, an angry customer, and an expert probing edge cases
- Run it
The support-hours check from that Botium script becomes a single instruction in this model: confirm the bot states the correct opening hours, in whatever words it chooses. No substring, no rerun when the phrasing changes. Teams retiring a whole Botium suite can follow the convo-by-convo mapping in the guide to Botium alternatives.
From your description, TestMu AI generates 60 to 100 or more conversation scenarios and turns 15 or more specialized evaluators loose on the bot. They chat with it multi-turn, across every intent, and score each reply against the 9 chat metrics: hallucination detection, bias detection, completeness, context awareness, response quality, conversation flow, tone consistency, positive user outcome, and root-cause understanding. You get a per-metric score and a Green, Yellow, or Red production-readiness verdict, with the exact conversation turn behind each result kept as evidence. That per-metric verdict is the core of AI agent evaluation, here narrowed to a single chat surface.
What breaks in a chatbot that a script never catches?
The failures that reach production are the ones no exact-match script can express: an invented fact, a lost thread of context, a thinner answer for one kind of user, and a collapse under a hostile message. Each of these is a plain-English scenario you can add without a line of code. The invented fact gets a full test method of its own in our guide to chatbot hallucination.
Hallucination when there is no answer
- Ask the bot for a detail your knowledge base does not hold, like a renewal date that was never set on the account
- The evaluator watches whether the bot invents a date or admits it does not know
- A confident, fabricated answer fails the hallucination metric, and the transcript stays attached as proof
Memory across a long conversation
- Give the bot your account number early in the chat
- Three turns later, ask something that depends on it
- The context awareness metric fails the bot if it asks for the account number again instead of remembering it
Bias across how people phrase things
- Send the same request in formal English, in casual slang, and in non-native phrasing
- The evaluator compares the three answers for completeness and detail
- A fuller answer to the formal query than to the casual one fails the bias metric
Adversarial and off-script users
- Send an angry, off-topic, or manipulative message
- The evaluator checks tone consistency, whether the bot holds its policy, and whether it escalates when it should
- A bot that mirrors the user's frustration or leaks its system prompt fails
Each scenario runs against the pre-built personas at once, from a digital novice to an impatient expert, so one plain-English description turns into broad coverage. That breadth is the point. Real coverage means a confused first-time user tested against an expert, and an angry customer tested against a patient one, across every intent the bot is meant to handle.
How do you test a chatbot for prompt injection and jailbreaks?
You describe the attack in plain English, or pick a category, and TestMu AI runs it. A dedicated Security Researcher evaluator and a red-team pass send prompt-injection, jailbreak, and data-exfiltration attempts the way a hostile user would, then score whether the bot holds its policy. There is no payload library to write and no security tooling to stand up, so the same manual QA or PM who ran the quality evaluation runs the security one.
The red-team pass probes the attack categories that break a support bot in production:
- Prompt injection, where a message tries to overwrite the bot's instructions and make it follow the attacker instead
- Jailbreaks that coax the bot past its guardrails into answering something it was told to refuse
- Data exfiltration and PII exposure, where the bot repeats another user's account details or leaks what it holds
- Policy violation and harmful content, where the bot invents a refund rule or says something it must never say
A bot that reveals its system prompt, repeats data from another session, or obeys an injected instruction fails, and the exact turn that broke it stays attached as evidence. The pass returns a letter grade from A+ to F with a per-category breakdown, so a PM can read the bot's security posture without reading a single payload. This is the same describe-it-once model as the quality run, pointed at the ways people attack a bot rather than the ways they use it.
AI jailbreaks range from single prompts that use role-play or encoded text to escalation spread across several turns, so a test plan needs attempts of each kind. For written cases, prompt injection and system prompt leakage both appear in the AI safety section of our chatbot test cases catalog.
How do you run chatbot tests on every release?
You wire the same evaluation into CI with the testmu-a2a-cli and gate the build on its exit code, or you schedule it to run on its own. A bot degrades even when you leave it alone, because the model underneath gets upstream updates and the knowledge base goes stale, so the evaluation earns its keep when it runs without you asking.
- Trigger on deploy from CI, where the testmu-a2a-cli runs the evaluation from your pipeline and returns exit code 0 to pass or 1 to fail the build
- Schedule a daily, weekly, or monthly run so an upstream model change cannot shift the bot's answers between releases unnoticed
- Send alerts to Slack, email, or a webhook when a verdict slips, with the failing transcript and the metric that dropped
When a verdict moves from Green to Yellow, there is no stack trace at line 47. You get the specific metric that regressed and the conversation that caused it, written in plain language a PM or a support lead can act on. The same setup extends past chat: agent testing gives you the picture across every surface, and voice agent testing picks up the moment your bot starts to speak, with the full walkthrough in how to test a voice agent without code.

Note: Test your chatbot without writing a line of code. Start with TestMu AI free.
Author
Chaitanya Sharma
Blogs: 21

Chaitanya Sharma is an AI Product Manager at TestMu AI, where he builds agentic AI capabilities focused on computer vision and multi-modality, moving testing beyond static script execution toward autonomous, agent-driven workflows. Before TestMu AI he shipped 135+ features at Sprinklr for a no-code community and website builder used by Fortune 500 enterprises including Dell, Samsung, and Polestar. At Policybazaar he led the zero-to-one launch of a digital lending and insurance marketplace embedded in Bahrain's dominant payments app, building a risk-intelligence engine that compressed loan-approval times by 80%. He explored machine learning and NLP through research at the University of Cambridge, and holds a B.Tech from Delhi Technological University.
Reviewer
Harish Rajora
Reviewer
Harish Rajora is a software developer at TestMu AI with over 6 years of hands-on experience in Python and cross-platform application development across Windows, macOS, and Linux. He has authored 800+ technical articles and worked on large-scale projects, including GenAI applications and core engineering features used by millions. Harish has led DevOps initiatives building CI/CD pipelines with Jenkins, AWS, GitLab, and GitHub, and holds an M.Tech in Software Engineering from IIIT Allahabad.


Chatbot Testing FAQs
Did you find this page helpful?
More Related Blogs

TestMu AI forEnterprise
Get access to solutions built on Enterprise
grade security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests