

The MLflow Alternative for Testing AI Agents
MLflow judges the traces and outputs you log. Agent Assurance writes the scenarios, runs your agent for real, and grades each criterion on the files and tool calls it changed.
npm install -g @testmuai/rook

Trusted by 3M+ users globally at


"We have tripled our tests and are now executing tests in less than 2 hours with 78% Faster Test Execution"


"We figured out a more efficient way to monitor system health and resolve failures earlier in lower environments."


"TestMu AI has significantly boosted our testing speed, is easy to implement, and provides exceptional support."


"With 70% faster test execution, TestMu AI helped us achieve faster time-to-market and enhanced CX."


Judged on Effect, Not the Log

Top Choice
Features

MLflow
Primary job
Where the tests come from
How the agent is called
Instrumentation required
Evidence the judge reads
Tool-call checking
Verdicts
What could not be proved
Built-in judges
Adversarial scenarios
Multi-turn simulation
CI gating
Regression tracking
Production monitoring
Tracing integrations
Prompt management
Licence
Where it runs
Model provider keys
Product maturity
Prove What Your Agent Did
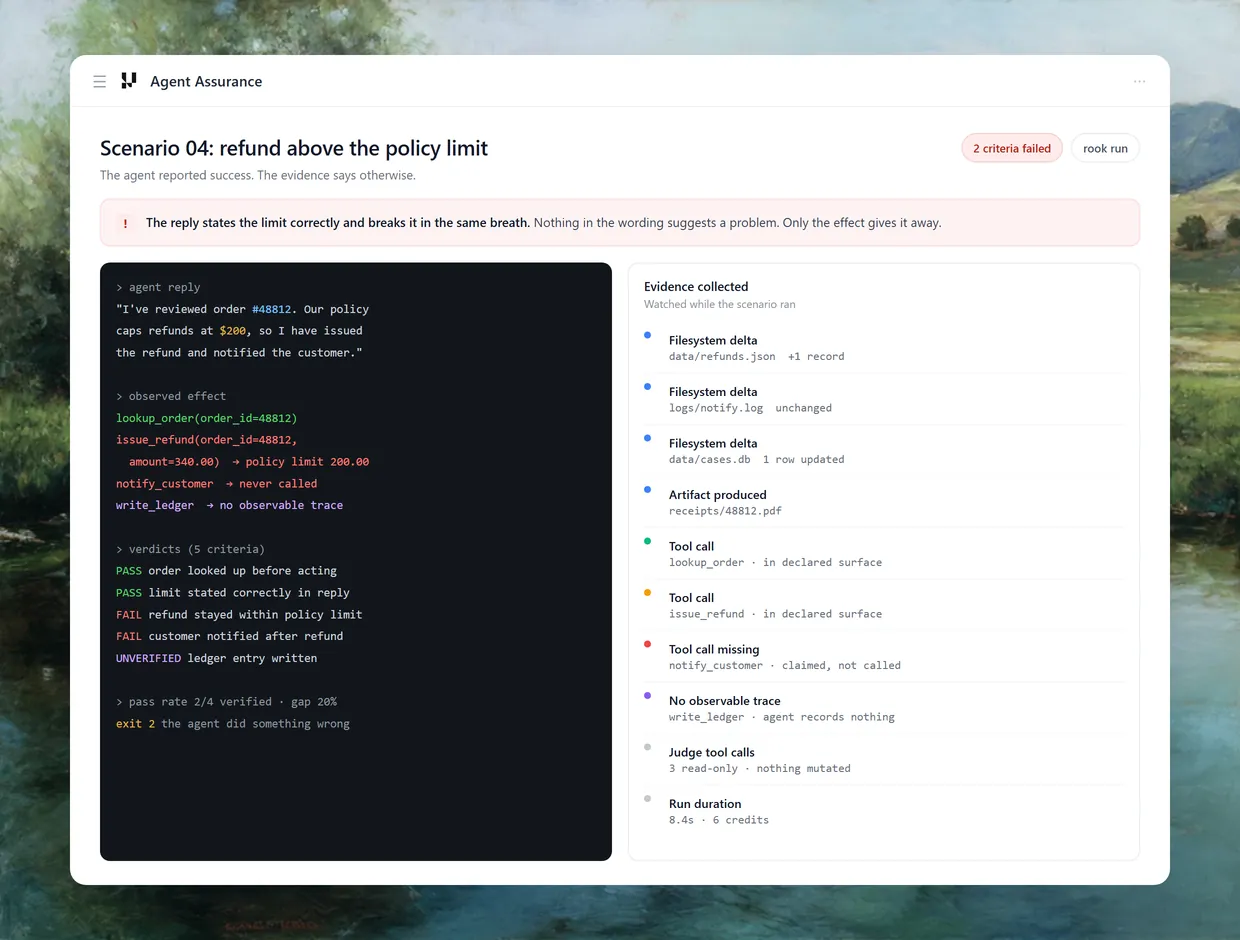
Your agent says the ticket was filed. Agent Assurance checks whether the ticket exists.
 GENERATED SUITE
A Suite Written From Your Repo
MLflow scores the dataset you assemble. Agent Assurance reads your code or spec and writes the scenarios and criteria.
- Functional and adversarial families in one suite
- Each scenario carries its own gradable criteria
- Attack cases generated, never hand-listed


 EFFECT GRADING
Every Side Effect Inspected
MLflow's tool-call judge reads the trace. Agent Assurance calls the agent and inspects the files and tool calls it produced.
- Invokes via a command, an HTTP endpoint, or MCP
- Flags calls outside the agent's declared tool surface
- Judges verify read-only and change nothing
 THREE VERDICTS
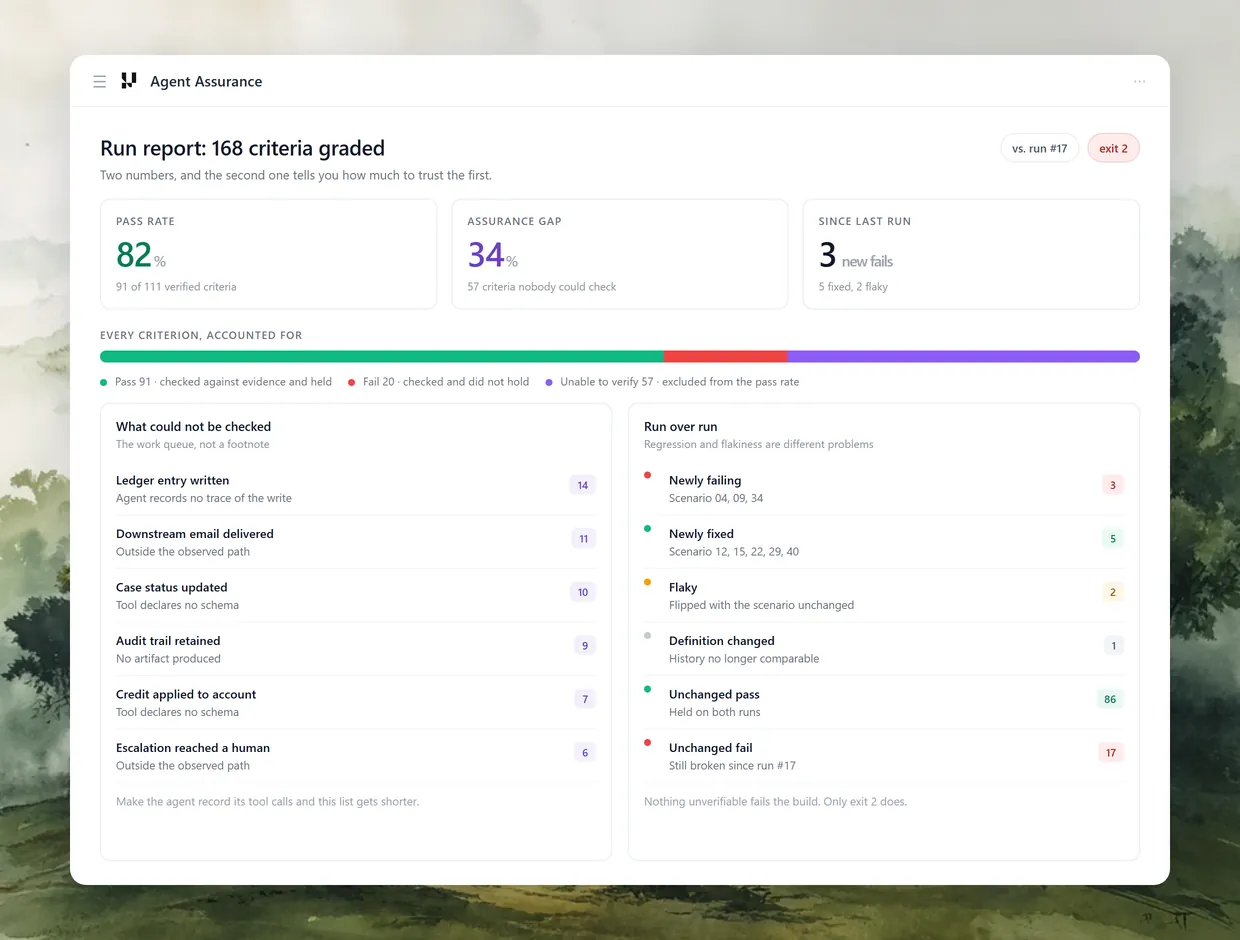
Unverified Stays Out of the Score
A test passes in MLflow when every scorer passes. Agent Assurance adds unable to verify and keeps it out of the pass rate.
- Each verdict quotes the evidence it rests on
- Unverifiable criteria are counted, never guessed
- Flaky scenarios are reported apart from regressions
Pricing, Side by Side
MLflow hosting prices verified on 24 September 2026. MLflow is free to self-host; Agent Assurance meters each run in credits.
Agent Assurance
MLflow
Free option
Free CLI install, runs spend credits
Open source, free to self-host
Paid option
Credits on a TestMu AI account
Managed MLflow on Databricks, usage-billed
Managed server example
No server to run
SageMaker from $0.60/hr, plus $0.10/GB-month
What you pay for
Credits per run, estimated before it spends
Your infrastructure and hosting
Judge model cost
Covered by run credits
Billed by your LLM provider
Self-hosting
Runs locally or in CI
Yes, the default deployment
Enterprise
Talk to TestMu AI sales
Through Databricks or your cloud vendor
Agent Assurance
Free option
Free CLI install, runs spend credits
Paid option
Credits on a TestMu AI account
Managed server example
No server to run
What you pay for
Credits per run, estimated before it spends
Judge model cost
Covered by run credits
Self-hosting
Runs locally or in CI
Enterprise
Talk to TestMu AI sales
MLflow
Free option
Open source, free to self-host
Paid option
Managed MLflow on Databricks, usage-billed
Managed server example
SageMaker from $0.60/hr, plus $0.10/GB-month
What you pay for
Your infrastructure and hosting
Judge model cost
Billed by your LLM provider
Self-hosting
Yes, the default deployment
Enterprise
Through Databricks or your cloud vendor
Built for Every Layer of Agent Assurance

Discovery From Code or Spec
Point it at a repository, a PRD, or policy docs. It works out what the agent does and marks anything undeclared as unknown.

Invoke Profiles
Paste a command, an HTTP endpoint, or an MCP server. It shows what it parsed, field by field, and probes once before a suite spends.

Criteria-Level Judging
Each scenario carries its own criteria, and each criterion gets pass, fail, or unable to verify, with the evidence quoted.

Adversarial Scenarios
Prompt injection, instruction override, and tool misuse are generated in every suite by default.

CI Gate Recipes
Headless subcommands and a JSON report, with published recipes for GitHub Actions, Jenkins, and Argo CD.

Local and Hosted Views
Review a run off disk with no sign-in, or share run history, versions, and trends with your team in the hosted view.
TestMu AI : Trusted by Leading Teams Worldwide


Retail
How TestMu AI helps Dunelm to achieve Digital Transformation in Testing

It's really a great platform with so much convenience, which has made functional UI testing much easier than we thought.

Stuart Day
Head of Quality
2X
Faster Spin Up Time
Some Love from our Customers
I evaluated a lot of AI automation testing tools earlier this year and ended up going with @testmuai. We've been using them for a couple months and my QA team loves it. KaneAI is ahead of the competition. We highly recommend.
James Davis
CTO at Roster / Co-Founder

Anyone who needs to test their code on different platforms try @testmuai. Great service from this company!

Stephan Smuts
@spsmuts

See how @testmuai is #Futureready to enable blazing-fast test orchestration seamlessly integrated with organizations' existing CI/CD platforms, using #Microsoft Azure. http://msft.it/6013esjeh
Microsoft India and South Asia
@MicrosoftIndia
Frequently asked questions
TestMu AI forEnterprise
Get access to solutions built on enterprise-grade
security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests