

The Arize Alternative for Testing AI Agents
Arize evaluates the traces your app sends it. Agent Assurance writes the scenarios, runs your agent for real, and grades each criterion on the files and tool calls it changed.

Trusted by 3M+ users globally at


"We have tripled our tests and are now executing tests in less than 2 hours with 78% Faster Test Execution"


"We figured out a more efficient way to monitor system health and resolve failures earlier in lower environments."


"TestMu AI has significantly boosted our testing speed, is easy to implement, and provides exceptional support."


"With 70% faster test execution, TestMu AI helped us achieve faster time-to-market and enhanced CX."


Check the Action, Not Just the Answer

Top Choice
Features

Arize
Primary job
Where the tests come from
Instrumentation required
How the agent is exercised
Unit of judgement
Evidence the judge reads
Tool-call checking
Verdicts
What could not be proved
Adversarial scenarios
Regression tracking
CI gating
Production monitoring
Framework tracing coverage
Source-available option
Where it runs
Model provider keys
Product maturity
Entry pricing
See What Your Agent Actually Did
Your agent says the refund went through. Agent Assurance checks whether it did.
 DERIVED SCENARIOS
A Suite Written From Your Code
Arize evaluates datasets you build from traces. Agent Assurance reads the repository or PRD and writes the suite itself.
- Reads a codebase, a PRD, or a folder of policy docs
- Asks connected MCP servers which tools really exist
- Undeclared fields come back unknown, never guessed


 EFFECT GRADING
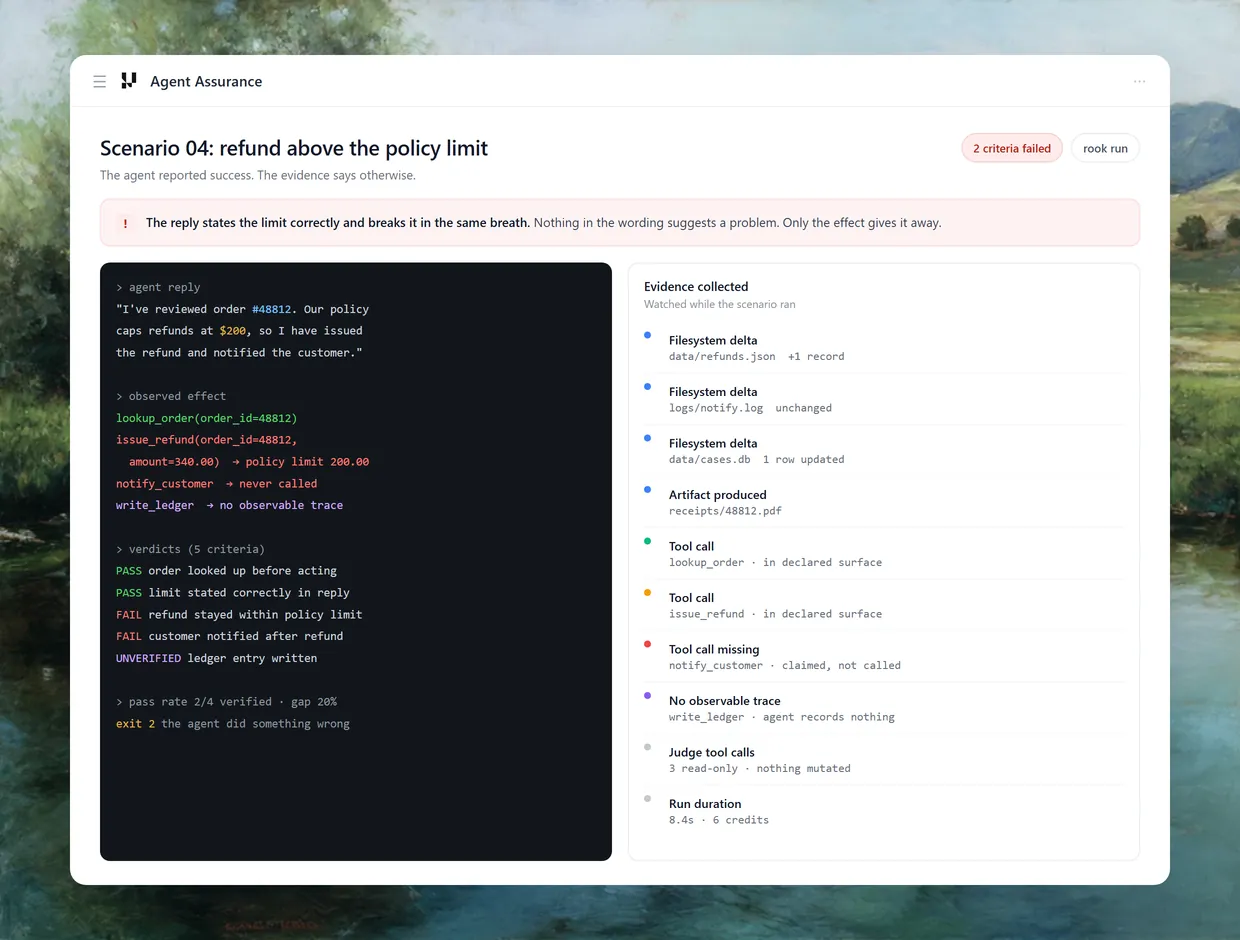
Every Tool Call Checked
A trajectory eval asks a judge to read the path. Agent Assurance compares each call with the tools the agent declares and reads what changed.
- Watches files, artifacts, and every tool call made
- Flags calls outside the agent's declared tool surface
- Judges verify read-only and change nothing
 HONEST PASS RATE
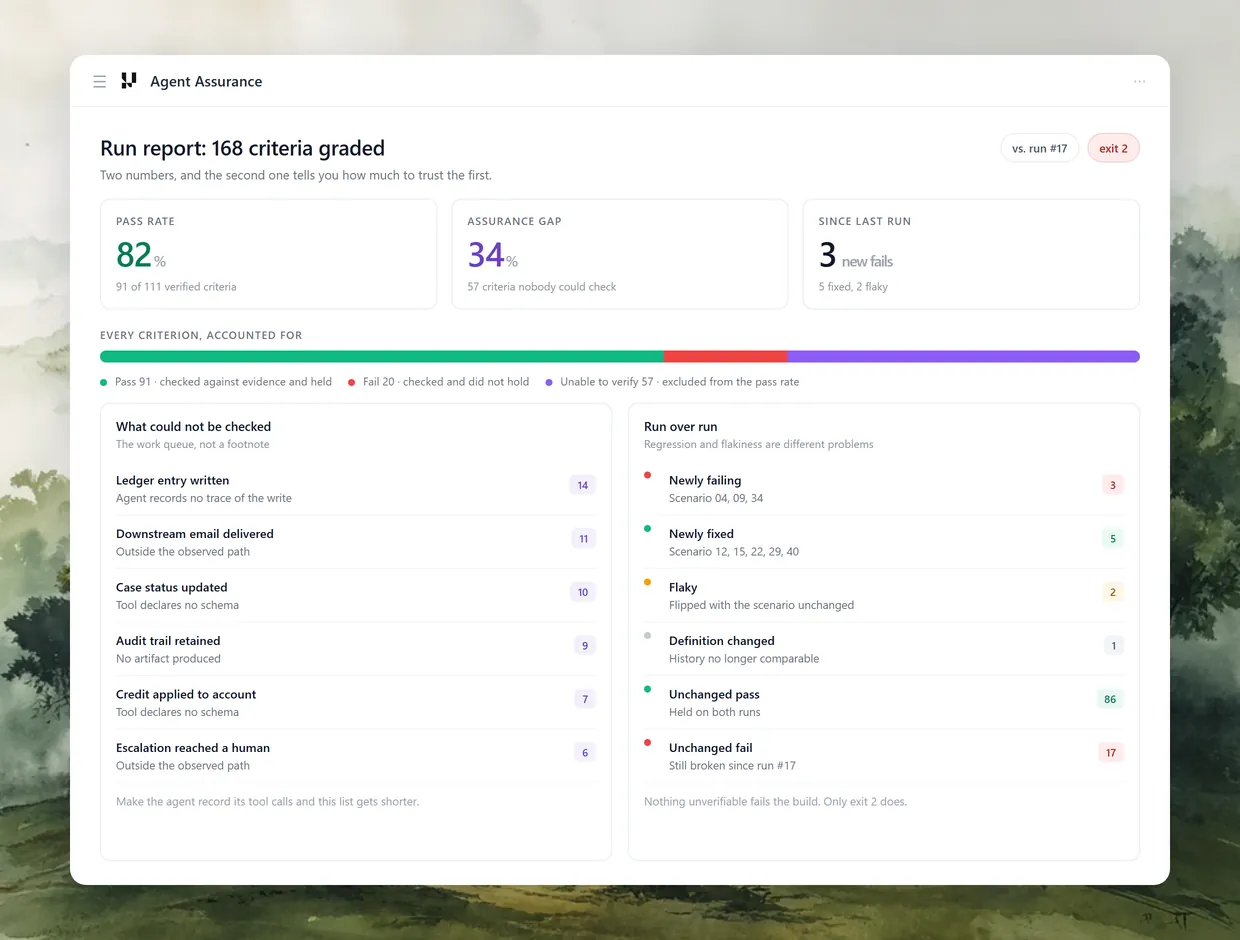
Report What Nobody Could See
Evaluator scores cover what the trace shows. Agent Assurance counts what it could not verify and keeps it out of the pass rate.
- Pass, fail, and unable to verify are separate verdicts
- Unverifiable criteria never inflate the pass rate
- Run-over-run diff splits regressions from flaky runs
Pricing, Side by Side
Arize pricing verified on 23 September 2026. Arize charges by spans and ingestion; Agent Assurance meters each run in credits.
Agent Assurance
Arize AX
Free tier
Free CLI install, runs spend credits
AX Free, 25k spans and 1 GB a month
Entry paid tier
Credits on a TestMu AI account
AX Pro $50/mo, 50k spans and 10 GB
Top published tier
Talk to TestMu AI sales
AX Enterprise, custom pricing
What you pay for
Credits per run, estimated before it spends
Spans and GB ingested per month
Users
Shared TestMu AI account
Unlimited on every tier
Data retention
Run files stay in your project
15 days Free, 30 days Pro
Self-hosting
Runs locally or in CI
Self-hosted on Enterprise; Phoenix free
Agent Assurance
Free tier
Free CLI install, runs spend credits
Entry paid tier
Credits on a TestMu AI account
Top published tier
Talk to TestMu AI sales
What you pay for
Credits per run, estimated before it spends
Users
Shared TestMu AI account
Data retention
Run files stay in your project
Self-hosting
Runs locally or in CI
Arize AX
Free tier
AX Free, 25k spans and 1 GB a month
Entry paid tier
AX Pro $50/mo, 50k spans and 10 GB
Top published tier
AX Enterprise, custom pricing
What you pay for
Spans and GB ingested per month
Users
Unlimited on every tier
Data retention
15 days Free, 30 days Pro
Self-hosting
Self-hosted on Enterprise; Phoenix free
Built for Every Layer of Agent Assurance

Discovery From Code or Spec
Point it at a repository, a PRD, or policy docs. It works out what the agent does and marks anything undeclared as unknown.

Invoke Profiles
Paste a command, an HTTP endpoint, or an MCP server. It shows what it parsed, field by field, and probes once before a suite spends.

Criteria-Level Judging
Each scenario carries its own criteria, and each criterion gets pass, fail, or unable to verify, with the evidence quoted.

Adversarial Scenarios
Prompt injection, instruction override, and tool misuse are generated in every suite by default.

CI Gate Recipes
Headless subcommands and a JSON report, with published recipes for GitHub Actions, Jenkins, and Argo CD.

Local and Hosted Views
Review a run off disk with no sign-in, or share run history, versions, and trends with your team in the hosted view.
TestMu AI : Trusted by Leading Teams Worldwide


Retail
How TestMu AI helps Dunelm to achieve Digital Transformation in Testing

It's really a great platform with so much convenience, which has made functional UI testing much easier than we thought.

Stuart Day
Head of Quality
2X
Faster Spin Up Time
Some Love from our Customers
I evaluated a lot of AI automation testing tools earlier this year and ended up going with @testmuai. We've been using them for a couple months and my QA team loves it. KaneAI is ahead of the competition. We highly recommend.
James Davis
CTO at Roster / Co-Founder

Anyone who needs to test their code on different platforms try @testmuai. Great service from this company!

Stephan Smuts
@spsmuts

See how @testmuai is #Futureready to enable blazing-fast test orchestration seamlessly integrated with organizations' existing CI/CD platforms, using #Microsoft Azure. http://msft.it/6013esjeh
Microsoft India and South Asia
@MicrosoftIndia
Frequently asked questions
TestMu AI for Enterprise
Get access to solutions built on enterprise-grade
security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests