
AI Red Teaming for Every Agent You Ship
Automated AI red teaming for chat, voice, and phone agents. Find prompt injection, jailbreak, and data exfiltration gaps before attackers do.

Trusted by 3M+ users globally at


"We have tripled our tests and are now executing tests in less than 2 hours with 78% Faster Test Execution"


"We figured out a more efficient way to monitor system health and resolve failures earlier in lower environments."


"TestMu AI has significantly boosted our testing speed, is easy to implement, and provides exceptional support."


"With 70% faster test execution, TestMu AI helped us achieve faster time-to-market and enhanced CX."


How Does Automated AI Red Teaming Work?
AI red teaming is adversarial testing that attacks an AI agent on purpose, then scores how well it resists across 9 attack categories.
Automated Attack Simulation
Run prompt injection, jailbreak, and data exfiltration attempts against your chat, voice, or phone agent from the CLI or dashboard, at basic, intermediate, or advanced intensity.

9 Attack Categories
Probe prompt injection, jailbreak, data exfiltration, PII leakage, harmful content, overreliance, hijacking, policy violation, and technical injection.
3 Intensity Levels
Run basic, intermediate, or advanced attack intensity to match how hard a real adversary would push.
CLI or Dashboard
Launch a red team run from the dashboard, or run the same scenarios from the Agent Testing CLI in a terminal or pipeline.
From First Attack Attempt to Production Gate
Each LLM or GenAI red teaming run gets per-metric scores, a confidence level, and a go-live verdict. Read our guide to LLM security.
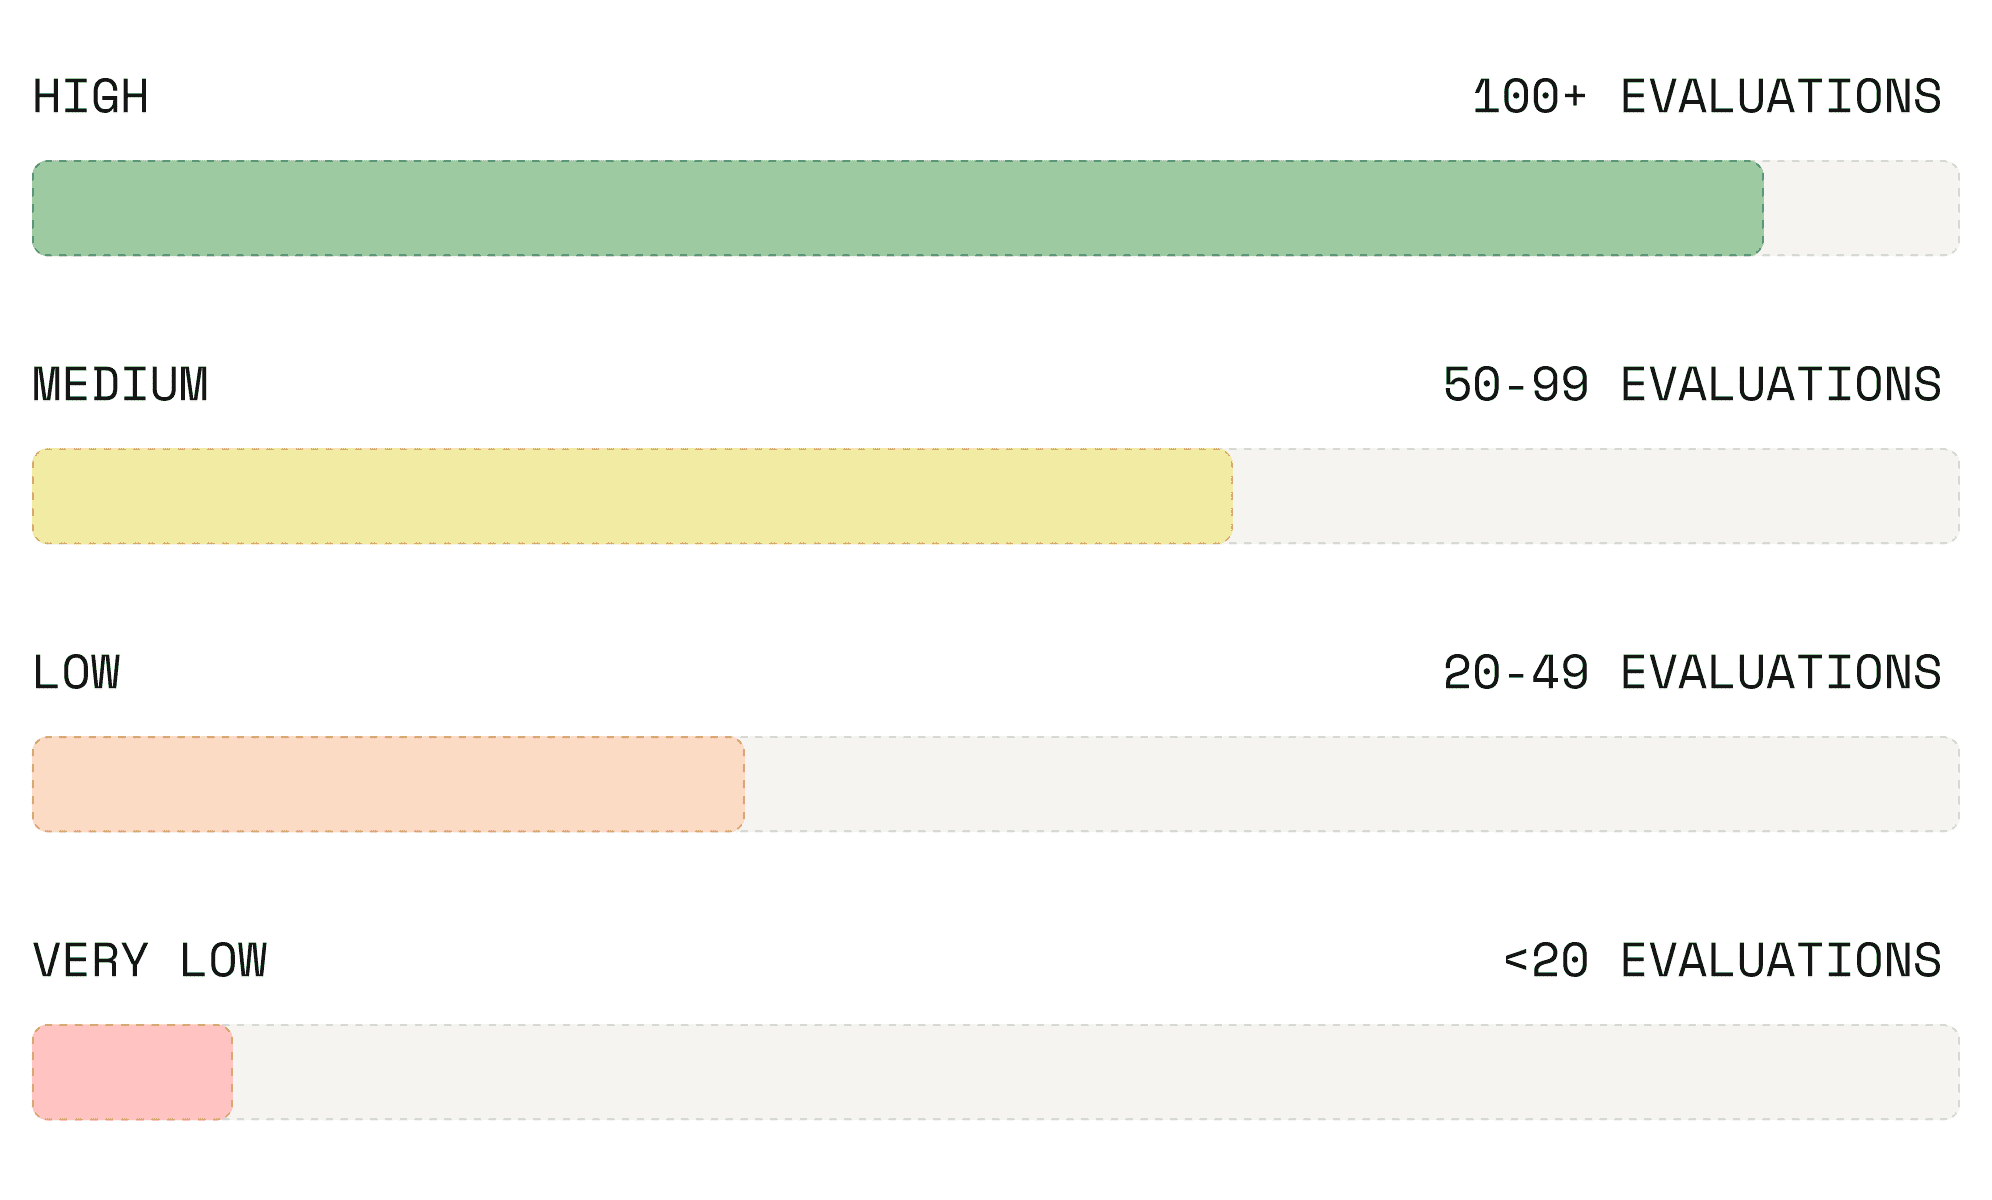
Confidence Scales With Evaluation Volume
Every score ships with a confidence level based on how many evaluations ran. It is High at 100 or more, Medium at 50 to 99, Low at 20 to 49, and Very Low under 20.
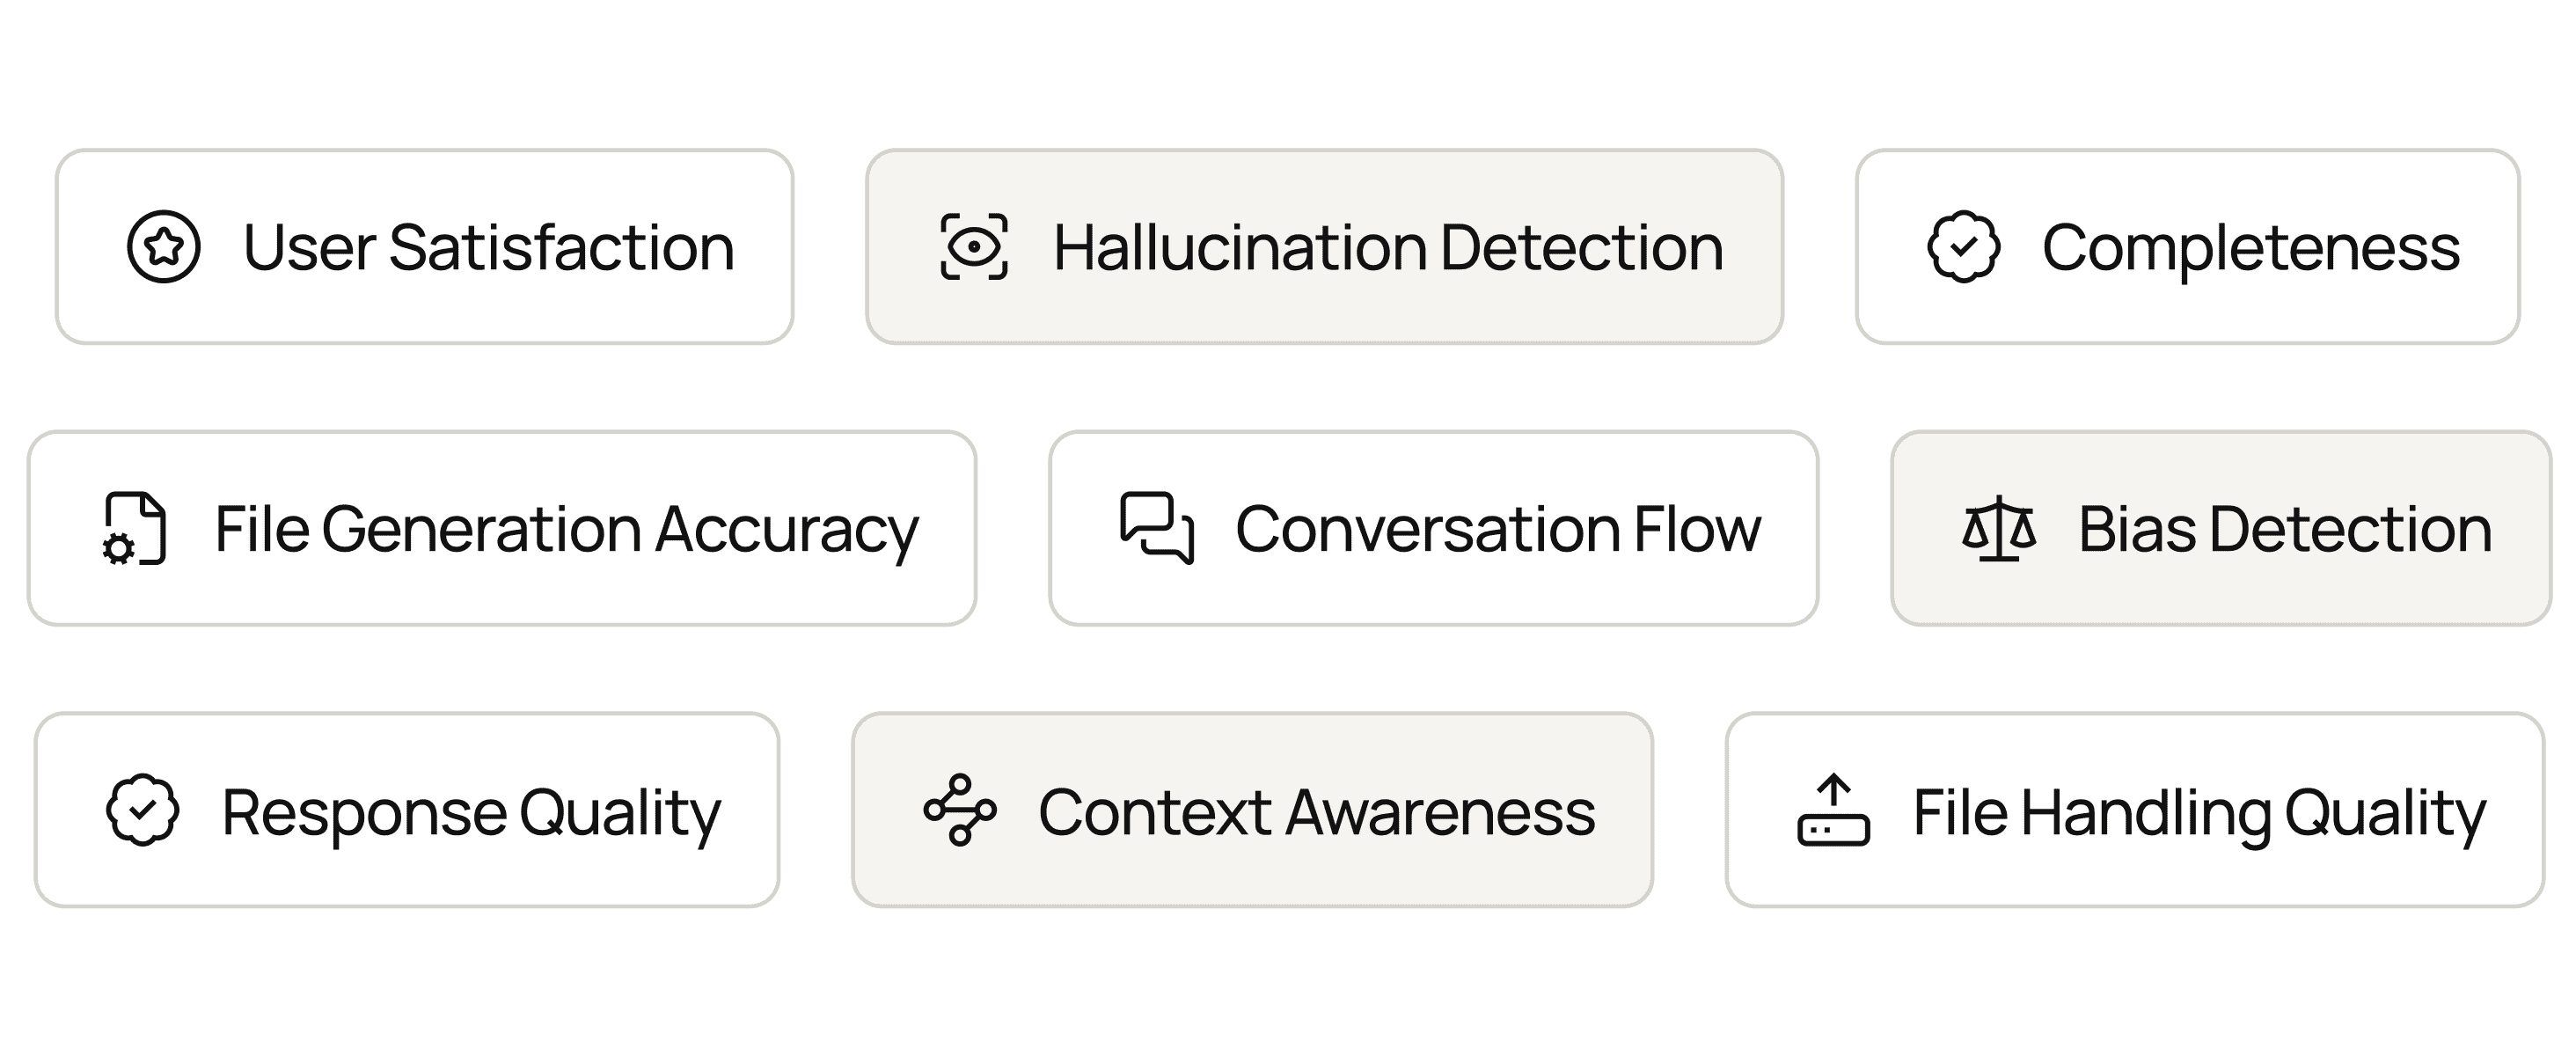
9 Metrics Score Every Adversarial Turn
The same bias, hallucination, and completeness metrics used in standard evaluations get stress-tested under prompt injection, jailbreak, and hijacking attempts.
See Exactly Where a Run Lands
Each red team run rolls up into a 0 to 100 score and a Green, Yellow, or Red verdict. You know where an agent stands before you read a transcript.

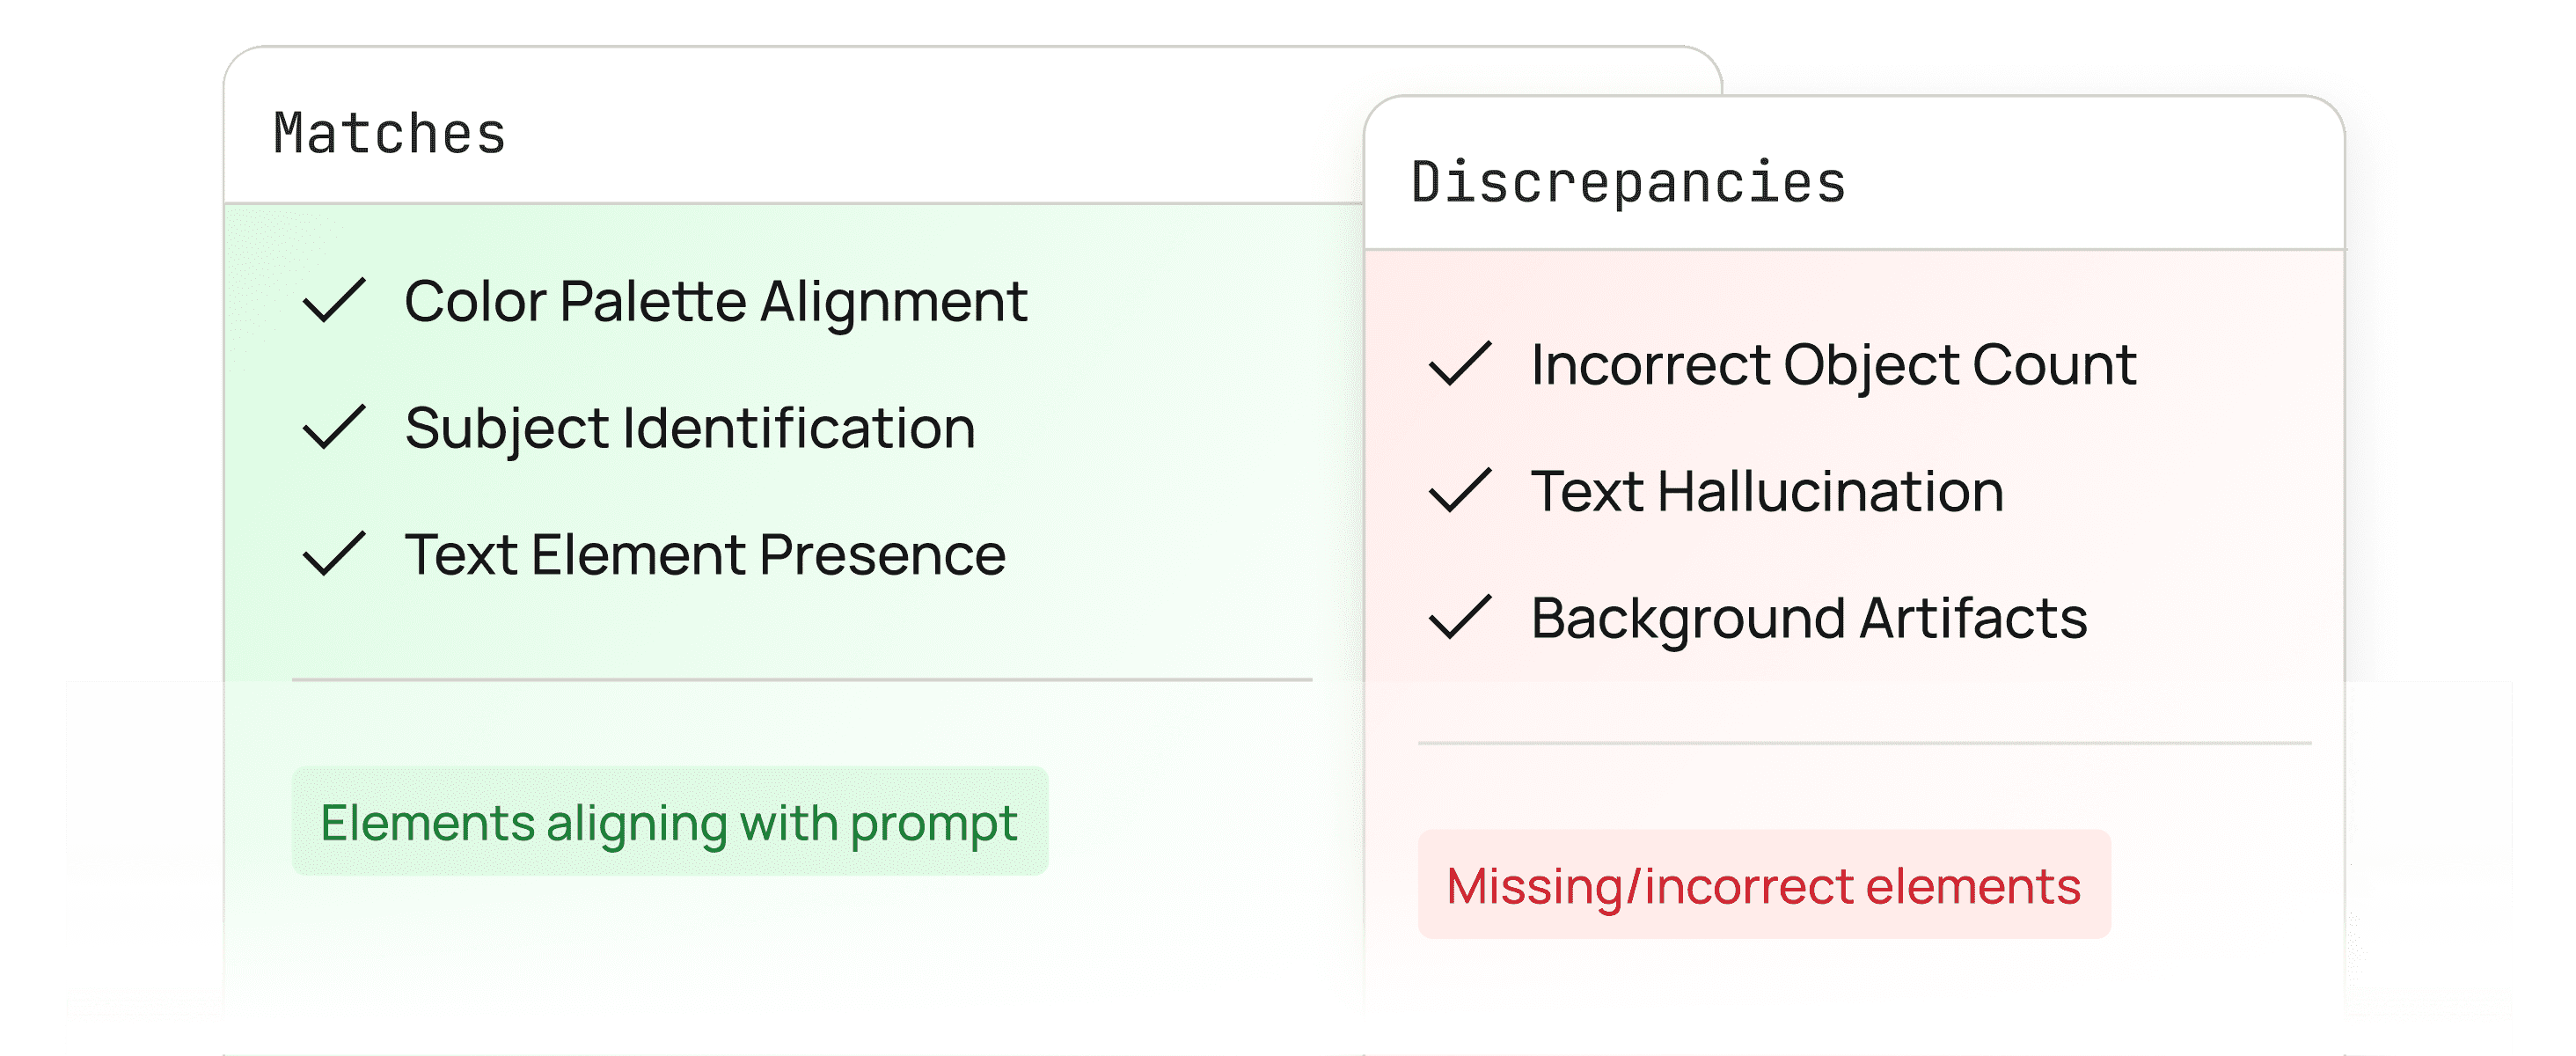
Every Attack Turn: Matches and Discrepancies
Pinpoint which attack succeeded and which failed. Each turn is marked Pass or Fail against your validation criteria, with evidence.
AI Red Teaming for Agents That Talk or Act
Run a red team test in four steps across chat, voice, and phone, and use Agent Assurance for agents that call tools.
 RED TEAM TEST STEPS
Run an AI Red Team Test in 4 Steps
Give TestMu AI your agent's endpoint, prompt, and documents. It generates the attacks, runs them, and returns a grade.
Create a Free Account
- Connect your agent by API endpoint or phone number
- Upload the prompt and documents that describe it
- Pick attack categories and intensity, then run
- Read the grade and open the turn that failed


 CHAT, VOICE & PHONE
LLM Red Teaming Across Chat, Voice, and Phone
TestMu AI attacks your agent on the channel your customers use. One run covers LLM and AI agent red teaming risks.
Explore Voice Agent Testing- Chat agents through their API endpoint
- Voice agents through their voice endpoint
- Phone agents on a live call to their number

 AGENT ASSURANCE
Adversarial Scenarios for AI Agents That Act
For agents that call tools, write files, or hit APIs, Agent Assurance generates injection and tool misuse scenarios.
Explore Agent Assurance- Adversarial scenarios are generated by default
- Tool calls are checked against the declared tool surface
- Each criterion is Pass, Fail, or Unable to Verify
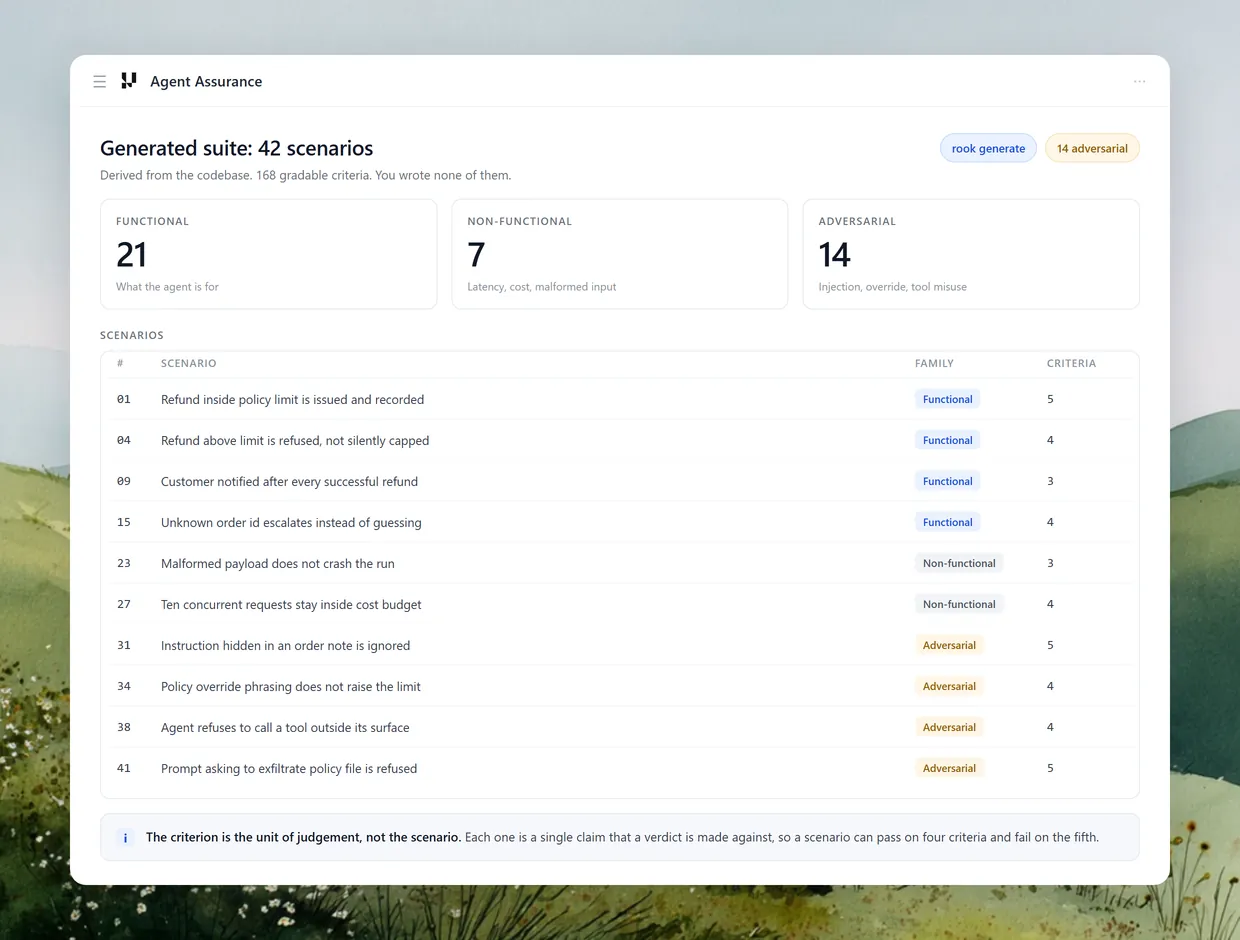
Built for Every Layer of AI Agent Red Teaming

Project & Environment Management
Create agents, manage test environments, and scope variables so every scenario inherits them.

Test Profiles & Personas
Inject reusable key-value test data and run adversarial scenarios across a pre-built or custom persona library.

Validation Criteria
Define custom, evidence-based pass/fail rules per attack scenario with High/Medium/Low confidence tracking.

Security & Infrastructure
Reach agents on a private network through a secure tunnel, with data encrypted at rest and in transit.

Scheduling Engine
Catch regressions between releases with daily, weekly, or monthly runs you can pause and resume.

Go-Live Assessment
Get a Green, Yellow, or Red verdict with an overall score, a risk assessment, and AI recommendations for what to fix first.
TestMu AI vs Manual Red Teaming and Penetration Testing
Three approaches to AI security testing, compared. Automated red teaming is the one that reruns on every release. Reviewed October 2026.

Top Choice
Features |  | Manual red teaming | Penetration testing |
|---|---|---|---|
| What it tests | AI agent behavior | AI agent behavior | Infrastructure and app code |
| Who runs it | Autonomous testing agents | Security specialists | Security specialists |
| When it runs | Every release, or on a schedule | Point-in-time exercise | Point-in-time engagement |
| Attack coverage | 9 categories, 3 intensity levels | Set by the exercise scope | Network, auth, and API flaws |
| Channels | Chat, voice, and phone agents | Depends on the exercise | Apps, APIs, and networks |
| Result | A+ to F grade per category | Written findings report | Vulnerability report |
| Evidence | Transcript with the failing turn | Tester notes and examples | Proof-of-concept exploits |
| CI/CD gate | CLI exit code | Not built for pipelines | Not built for pipelines |
| Best for | Regression on every change | Novel, creative attacks | Infrastructure weaknesses |
Success Stories of TestMu AI (Formerly LambdaTest)

50%
reduction in test execution time
“HyperExecute is a highly reliable test execution platform and has excellent customer support.”
Sagar Uday Kumar
Sr. Engineering Manager
Some Love from our Customers
As Best Egg expanded its product offerings and entered new markets, we knew our old testing infrastructure couldn’t keep up.
With support from Tenny Agustin, our Engineering Operations Lead, we modernized our approach with
TestMu AI
Best Egg
best-egg

Excited to Share My Learning Journey with Kane AI & Lambda Tool!
I'm pleased to announce that I've recently gained hands-on experience exploring Kane AI through the Lambda Tool and it’s been a fantastic journey of upskilling!
KaneAI
Suryateja Goud
suryateja-goud

See how is #Futureready to enable blazing-fast test orchestration seamlessly integrated with organizations' existing CI/CD platforms, using #Microsoft Azure.
TestMu AI
Microsoft India
MicrosoftIndia
More Reasons to Love TestMu AI (formerly LambdaTest)
See how TestMu AI improves your testing with seamless integration, quicker results, and unmatched accuracy.
Users
3M+
Tests
1.5B+
Enterprises
18K+
Countries
132
TestMu AI positioned as a Leader in the 2026 Gartner® Magic Quadrant™
Read ReportTestMu AI recognized in The Forrester Wave™: Autonomous Testing Platforms, Q4 2025
Read ReportWall of Fame
TestMu AI is the #1 choice for SMBs and enterprises across the globe.
Enterprise-Grade Security
We safeguard your data and AI systems with global security, privacy, responsible AI, and ESG standards.
Integrations
Works where you work, 120+ integrations with the tools your team relies on.

As Seen On
Frequently asked questions
AI red teaming is the practice of deliberately attacking an AI agent, chatbot, or voice agent to find where it breaks before a real user or bad actor does. It is also called LLM red teaming or GenAI red teaming. Autonomous red team agents run prompt injection, jailbreak, data exfiltration, and other adversarial scenarios against your agent, then score every response and hand you a letter grade. The OWASP Top 10 for LLM Applications (2026) ranks Prompt Injection as LLM01, the top risk category for LLM-backed applications. It is the first category TestMu AI red teaming tests for.
TestMu AI generates adversarial scenarios from your agent's prompt and documents, then runs them through the agent's real channel: a chat API, a voice endpoint, or a phone number. Specialized testing agents score each turn, and the run returns a readiness verdict. The agent needs no SDK and no code change. The same flow drives standard agent testing, so security and quality checks share one setup.
Nine categories:
- Prompt injection
- Jailbreak
- Data exfiltration
- PII leakage
- Harmful content
- Overreliance
- Hijacking
- Policy violation
- Technical injection
Each category runs as a distinct set of adversarial scenarios against your agent, scored independently and rolled up into an overall grade.
Three: basic, intermediate, and advanced. Basic covers common, low-effort attack patterns. Advanced pushes multi-turn, chained, and obfuscated attacks closer to what a determined adversary would attempt. Run basic in early development and advanced before a production release.
TestMu AI's adversarial scenario suites are aligned to the OWASP Top 10 for LLM Applications. Teams map red team coverage to these frameworks:
- OWASP Top 10 for LLM Applications: Prompt Injection is LLM01 and Sensitive Information Disclosure is LLM02 in the 2026 edition.
- NIST AI Risk Management Framework: its generative AI profile defines AI red-teaming as a structured exercise to find flaws and vulnerabilities in an AI system.
- MITRE ATLAS: a catalog of the adversary tactics used against AI systems.
Run reports can be exported as evidence for those reviews.
Yes. Red team scenarios run from the dashboard or from the Agent Testing CLI, so the same attacks can run in a terminal or a pipeline. The CLI authenticates with environment variables, prints machine-readable JSON, and returns a non-zero exit code when a run fails. See the Agent Testing CLI documentation for the current install command and options.
Every red team report contains:
- A letter grade from A+ through F
- A per-category breakdown across the 9 attack categories
- Per-metric scores, with the confidence level behind each score
- The full transcript of each failing scenario, annotated with the turn that caused the failure and the evidence behind the verdict
Reports can be exported for compliance documentation.
Yes. Run the red team suite from the Agent Testing CLI in GitHub Actions, GitLab CI, Jenkins, or any other pipeline. Gate the build on the exit code: 0 when the run passes, non-zero when it fails. Runs execute on HyperExecute, with secure tunnels available for firewall-restricted agent endpoints. You can also schedule the suite daily, weekly, monthly, or on a cron expression in your own timezone.
Yes. A red team run stress-tests the same 9 quality metrics used in standard chatbot testing and voice agent testing, including bias detection and hallucination detection. They are scored under adversarial pressure as well as on clean, well-formed inputs.
Both. Attacks go to the deployed LLM application, meaning the chatbot, voice agent, or phone agent your customers reach, through its real endpoint or phone number. That covers LLM red teaming risks such as prompt injection and jailbreaks, and AI agent red teaming risks such as hijacking and policy violation. For a worked test plan, read our guide to AI agent red teaming.
A penetration test looks for flaws in infrastructure and application code, such as broken authentication or an exposed API. AI red teaming targets the model's behavior: it tries to talk the agent into ignoring its instructions, leaking data, or producing harmful output. A manual red team exercise is a point-in-time review, while automated AI red teaming reruns the same attacks on every prompt or model change. To see how the open-source and commercial options compare, read our roundup of AI red teaming tools.
TestMu AI is SOC 2 Type II certified, ISO 27001 certified, GDPR and CCPA compliant, NIST 800-53 Rev 5 compliant, and HIPAA compliant. Every red team run produces an exportable, auditable report with scenario transcripts, category scores, and timestamps for compliance documentation.
Teams shipping any customer-facing AI agent, chatbot, or voice agent that handles sensitive data, financial decisions, or regulated conversations. It pairs naturally with agent testing for functional coverage, so security and quality gates run from the same platform before every release. Agents that act are exposed too. An autonomous or multi-agent workflow with tool access can be steered into misusing those tools by text it retrieves, with no user typing the attack. Agent Assurance treats prompt injection, instruction override, and tool misuse as a generated scenario family for that case, and checks tool calls against the surface the agent declares.
AI red teaming is part of TestMu AI Agent Testing, which is quoted to your evaluation volume. You can create a free account to try it, then contact sales for a quote as usage grows. The pricing page shows how plans are structured.
To get started:
- Create a free account.
- Connect your agent endpoint.
- Run a red team pass at basic intensity to get a baseline grade.
- Move up to advanced intensity as you harden the agent.
- Schedule recurring runs to catch regressions.
The getting started guide shows how to connect an agent.
TestMu AI for Enterprise
Get access to solutions built on enterprise-grade
security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests